 Your new post is loading...

|
Scooped by
mhryu@live.com
August 24, 11:54 AM
|
Efficient protein engineering is constrained by vast sequence space and limited experimental throughput, particularly for protein families that lack large mutational datasets. Here we combine Fanzor2 (Fz2) ortholog discovery, ωRNA scaffold engineering and EvoMax, a model-guided prioritization strategy for sparse-data engineering of compact eukaryotic Fz2 nucleases. EvoMax integrates iterative experimental profiling with Gaussian process regression, protein language models and inverse folding to navigate complex sequence-to-fitness landscapes. Applied to eukaryotic Fz2 nucleases, this strategy yielded a high-performance variant, FanzMAX v3-hLa, achieving up to 97% editing efficiency at the best-performing endogenous locus and a mean editing efficiency of ~33% across 19 endogenous loci, outperforming the established compact genome editors enNlovFz2 and enCnCas12f1 by more than 2.6-fold. In vivo editing of hPCSK9 in humanized mice supported the translational potential of optimized Fz2 editors. Together, these results establish EvoMax as an integrated strategy for engineering compact eukaryotic Fz2 genome editors and identify FanzMAX v3-hLa as a high-efficiency programmable nuclease for mammalian genome editing. Computational protein evolution with sparse data generates efficient small RNA-guided nucleases.
|
|
Scooped by
mhryu@live.com
August 23, 2:34 PM
|
DNA synthesis fidelity remains a critical bottleneck in large-scale gene assembly. Although conventional post-synthetic purification methods (e.g., HPLC, PAGE) and enzymatic mismatch-cleavage strategies offer partial solutions, they often suffer from limited throughput, high cost, and incompatibility with automated workflows. To overcome these limitations, we developed an integrated, sensitive and high-throughput error-correction platform that combines a rationally engineered E. coli MutS protein (eMutS) with a biotin-streptavidin magnetic-bead separation system (eMBS). Specifically, a single point mutation (E38N) was introduced into eMutS to enhance mismatch-recognition specificity while suppressing non-specific binding to perfectly matched DNA by optimizing key residue-base interactions of enhanced π-π stacking and direct hydrogen bond formation. Two cysteine mutations (L157C/G233C) were further incorporated to promote disulfide bond formation, which strengthens the affinity toward all three error types and enhances structural stability. The resulting eMutS-L157C/G233C-E38N-biotin fusion protein which was immobilized onto streptavidin-coated magnetic beads, enables rapid and efficient magnetic separation of error-containing heteroduplexes from error-free homoduplexes. In terms of superior performance with mixed DNA substrates, eMBS reduces total errors by 13.1∼63.3% (n = 3 independent experiments) in pools starting with 73.6∼98.6% correct sequences, and achieves an error-free DNA ratio of 99.1%. By eliminating labor-intensive electrophoresis or column purification steps, this sensitive, versatile and high-throughput workflow can support high-fidelity DNA synthesis.
|
|
Scooped by
mhryu@live.com
August 23, 2:18 PM
|
Accurate computational prediction of enzyme function, standardized by Enzyme Commission (EC) numbers, is essential for large-scale genome annotation and generative enzyme design. However, it remains unclear whether state-of-the-art predictors learn the intrinsic structural determinants of catalytic activity or merely rely on global sequence similarity to annotated homologues. To address this gap, we introduce EnzymARC, a novel benchmark dataset of putative non-functional decoy sequences generated via structure-guided, systematic disruption of active sites (targeting catalytic residues and surrounding 5 A, 10 A, and 15 A radii) from experimentally annotated enzymes. We evaluated three distinct prediction paradigms against this dataset: homology-based annotation (DIAMOND), contrastive learning with protein language models (CLEAN), and a deep learning model incorporating non-enzyme discrimination (DeepEC). Our findings reveal that current models are highly vulnerable to phylogenetic shortcuts. Both DIAMOND and CLEAN exhibited false positive rates exceeding 90% for low-perturbation decoys, confidently assigning the original EC numbers despite the destruction of the catalytic machinery. While DeepEC demonstrated improved sensitivity at higher perturbation levels, highlighting the benefit of negative training examples, all models struggled to identify targeted active-site disruptions. We demonstrate that modern EC predictors largely fail to distinguish catalytically incompetent variants from functional enzymes, and we propose that integrating structure-aware negative examples into both training and benchmarking is critical for developing functionally robust models in computational enzymology.
|
|
Scooped by
mhryu@live.com
August 23, 1:02 PM
|
Microbial metabolism is a complex, emergent system driven by the coordinated interplay of intricate and dynamic molecular processes. To elucidate cellular behavior and enable biotechnological applications, quantitative models that address the inherent complexity of metabolism have been developed from a resource allocation perspective. Here, we synthesize recent advances in coarse-grained resource allocation frameworks and their applications in understanding microbial physiology and guiding gene circuit design. These frameworks reveal global regulatory constraints and predict cellular adaptation to nutrient and environmental changes. In addition, they enable the quantification of metabolic costs, the dissection of circuit–host interactions, and the development of strategies for burden mitigation. Collectively, these modeling frameworks provide a powerful platform for uncovering quantitative principles of microbial growth and engineering robust synthetic biological systems.
|
|
Scooped by
mhryu@live.com
August 22, 11:43 PM
|
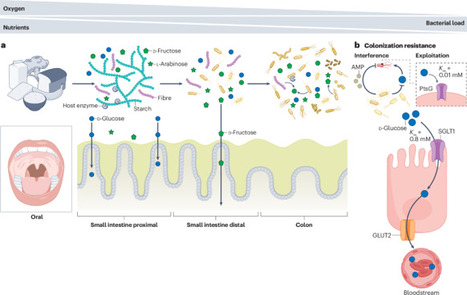
Enterobacteriaceae are facultative anaerobic bacteria that commonly colonize the gut and include both commensals and diverse pathogens. They can flexibly adapt their metabolic strategy to grow in the intestinal environment. As Enterobacteriaceae blooms are linked to enteric disease and the dissemination of antibiotic resistance, a deeper understanding of the factors that drive their expansion is needed. In the healthy intestine, Enterobacteriaceae subsist on low concentrations of diet-derived and mucus-derived monosaccharides that feed glycolysis and mixed-acid fermentation. Inflammation reshapes this niche as immune-derived oxidants generate new terminal electron acceptors, such as nitrate or tetrathionate, and facilitate oxygen diffusion into the gut lumen, thereby expanding facultative anaerobes and broadening the range of usable substrates. In this Review, we discuss recent evidence across E. coli, Citrobacter rodentium, Klebsiella spp. and Salmonella Typhimurium to define a conserved, monosaccharide-fuelled programme for colonization and its inflammatory remodelling. Competition with commensal bacteria for these nutrients underpins colonization resistance, and genetic differences can determine competitive fitness. Metabolism lies at the core of these ecological dynamics, and recognizing its central role will help guide the design of future therapies. In this Review, Schubert and Hardt explore the metabolic strategies that Enterobacteriaceae use to establish themselves in the gut, and how they adapt to inflammatory conditions in this environment.
|
|
Scooped by
mhryu@live.com
August 22, 11:18 PM
|
The affordability and high-throughput capabilities of Oxford Nanopore Technologies (ONT) have democratized genomic sequencing, yet the complexity of bioinformatics environment setup and analysis remains a barrier for many biologists. microbiONT addresses this gap by providing a user-friendly, privacy-focused platform that features a streamlined, one-command installation process. Integrating a local Large Language Model (Llama 3.1) with an intuitive graphical interface, microbiONT serves not only as an analysis tool but also as an AI copilot to assist users in learning bioinformatics concepts. By translating natural language requests into executable commands and simplifying deployment, microbiONT empowers non-experts to perform rigorous or custom 16S/18S amplicon analysis locally. This ensures rapid data insights without the need for command line use. Beyond its AI-integrated GUI, the novelty of microbiONT lies in its fully localized, highly accurate, and privacy-preserving architecture for flexible data analysis.
|
|
Scooped by
mhryu@live.com
August 22, 10:52 PM
|
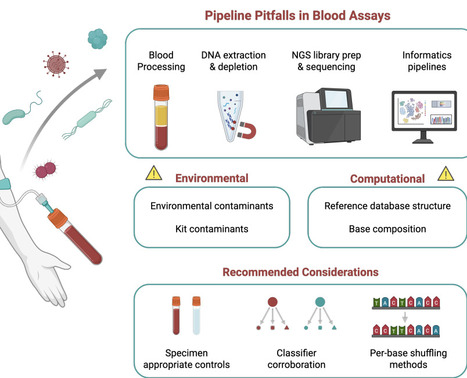
Circulating microbial DNA (cmDNA) has been proposed as a non-invasive cancer biomarker, but most evidence comes from cancer-sequencing datasets not designed for microbial analysis and lacking contamination controls. Whether reported signatures reflect biology or artifact is unclear in low-biomass specimens, where standard taxonomic pipelines are prone to systematic error. In a tightly controlled pilot study of metastatic castration-resistant prostate cancer, we profiled plasma cell-free DNA (cfDNA) and buffy-coat genomic DNA (gDNA) from two patients and two healthy volunteers alongside mock blood-draw and reagent controls, each with and without host-DNA depletion. Much of the apparent cmDNA structure, including its agreement with a published cancer-microbiome catalog, is explained by base composition and reference-database architecture rather than authentic biology, and short-read k-mer pipelines cannot separate the two on their own. We find little positive evidence of an authentic circulating microbial signal, though our small sample cannot prove its absence. To limit false discovery in low-biomass metagenomics, we recommend specimen-matched negative controls, corroboration with a conservative second classifier, per-base shuffling (with GC-matched synthetic reads as a stricter floor), and GC-aware analysis.
|
|
Scooped by
mhryu@live.com
August 22, 10:31 PM
|
Small open reading frames (sORFs) are a potentially rich, yet error-prone, source of antimicrobial-peptide (AMP) candidates: short sequences are readily prioritized by AMP classifiers but may derive from incomplete gene calls. We developed a genome-context-aware discovery workflow that separates AMP-like sequence properties from evidence for a complete, recurrent coding locus. From 649,653 RefSeq assemblies representing 327 clinically relevant bacterial species, species-aware clustering and length filtering yielded 4,442,548 representative 10-100-aa sequences. AmpScanner v2, Macrel and AMPlify identified 585 non-haemolytic records supported by all three models. However, genome-context auditing of 11,918 mapped candidates showed that 529 of 536 mapped consensus candidates were supported exclusively by partial ORFs near contig termini. By contrast, 3,382 candidates had at least one complete non-edge occurrence; 1,069 recurred in ≥2 assemblies and 251 in ≥10 assemblies. We therefore assembled a 20-peptide panel through two explicitly labelled routes: sequence/structure-led selection (n=8) and genome-supported selection (n=12). Broth microdilution against Escherichia coli ATCC 25922 and Staphylococcus aureus ATCC 25923 identified low-micromolar activity in both routes. CAND_04141, a recurrent complete non-edge candidate, had the strongest combined profile (MICs of 4 and 2 μM, respectively), while CAND_07825 and CAND_04265 were also active at low micromolar concentrations. In plate-count MBC assays, all three advanced peptides achieved ≥3-log10 reductions at 128 μM. These findings show that high classifier agreement is not a substitute for genomic evidence and provide an auditable framework for prioritizing both synthetic AMP-like sequences and candidate genome-encoded peptides.
|
|
Scooped by
mhryu@live.com
August 22, 5:59 PM
|
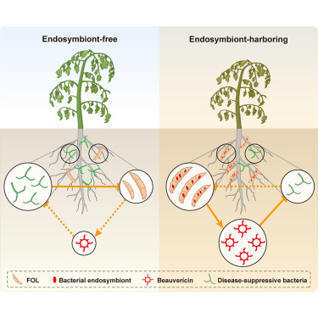
The mechanisms by which bacterial endosymbionts (bacteria living within fungal cells) enhance the fitness and virulence of fungal pathogens remain poorly understood. Here, we report that the tomato Fusarium wilt pathogen Fusarium oxysporum f. sp. lycopersici (FOL) hosts Achromobacter spp. endosymbionts that enhance fungal virulence. This virulence potentiation is partially dependent on interactions with the native rhizosphere microbiota. We show that bacterial endosymbiont-harboring FOL reshapes the rhizosphere bacterial community during pathogen infection and decreases the abundance of disease-suppressive bacteria, including Streptomyces spp. taxa. This inhibitory effect is mediated by bacterial endosymbiont-stimulated production of beauvericin (an antibacterial cyclic hexadepsipeptide) by FOL. Together, our findings reveal a tripartite interaction in which a fungal pathogen leverages its bacterial endosymbiont to weaken rhizosphere microbiome-based disease suppression by inhibiting plant-protective bacterial taxa. This work highlights how cross-kingdom symbioses can modulate pathogen ecology and virulence in soil environments.
|
|
Scooped by
mhryu@live.com
August 22, 4:15 PM
|
Transcription underpins the expression of genetic information and is viewed as a series of independent initiation and termination events. In bacteria, promoters and terminators of transcription are therefore considered distinct regulatory elements. Here, we challenge this view. Genome-scale analyses reveal that promoters and terminators are extensively coupled. Thus, initiation and termination sites, for adjacent transcription units, frequently overlap. This conserved organization arises because the DNA sequences, which direct termination, also contribute to promoter function. This couples neighboring transcription units and generates regulatory interference between RNA polymerases. These findings define a universal mechanism for coordinating transcription across bacterial genomes.
|
|
Scooped by
mhryu@live.com
August 22, 2:26 PM
|
Microorganisms interact through the exchange of metabolites and competition for shared substrates, and this metabolic coupling shapes the composition and function of microbial communities. Community flux balance analysis (cFBA) can predict such behavior - the maximum community growth rate, the metabolic fluxes and the relative abundances of the species - from stoichiometric models of their metabolism, but existing formulations are either complex and hard to scale as communities grow or cannot predict optimal growth rates. Here we present a physiology-based formulation of cFBA in which each species' metabolism is reduced to a few macrochemical equations, one for each 'metabolic mode' the species can use, and the whole community is then solved as a single linear program. From this, the method predicts the optimal composition of the community, its maximum growth rate, the metabolites exchanged between the species, and the net conversion the community carries out as a whole; its ecological service. This reduction makes it far simpler to build and solve models of larger communities. We illustrate the approach on a two-species synergistic community that can be verified by hand, apply it to a five-member anaerobic digestion community, and use it to predict the metabolic interactions of a genome-scale syngas-fermenting coculture. Characterizing these communities at their optimal steady states, we show that each species is driven to a distinct metabolic strategy. We discuss the method both as a practical tool for larger microbial communities and as a means of uncovering the ecological principles that govern them.
|
|
Scooped by
mhryu@live.com
August 22, 1:54 PM
|
Surface layers (S-layers) are highly ordered, paracrystalline protein lattices that form the outermost envelope of many bacteria and archaea. Although widespread, their functions and structural organization are only recently being elucidated at molecular resolution. This review addresses S-layer structure and function in Gram-positive bacteria, with emphasis on emerging insights into lattice-forming self-assembly and the mechanisms by which S-layers attach to the cell wall. Recent work highlights the role of Gram-positive S-layers as exoskeletons that provide organisation and mechanical stabilization of the cell envelope, and discusses their involvement in host interactions and stress tolerance. Although crystallinity is central for S-layer function, these lattices must also incorporate intrinsic plasticity to accommodate cell curvature and permit cell growth and division. S-layers and associated proteins are increasingly thought to act as active organisers of the cell envelope, and can undergo shedding or remodelling in response to changing environmental conditions.
|
|
Scooped by
mhryu@live.com
August 22, 1:27 PM
|
The mechanosensitive channel of large conductance (MscL) is a tension-gated, pore-forming protein that acts as a safety valve to protect bacteria from osmotic lysis. E. coli MscL (EcMscL) was the first mechanosensitive channel discovered and subsequently served as a model system for understanding mechanical sensing, becoming one of the most decorated and well-studied systems. Despite extensive biophysical and functional characterisation spanning several decades, the precise mechanism of EcMscL gating has been poorly understood due to the lack of high-resolution structural information. Herein, we solve two EcMscL structures by cryoEM in the closed conformation in DMPC and DOPC lipid nanodiscs. Using PELDOR/DEER spectroscopy, we screen conditions and identify that in DSPC lipids, the EcMscL conformational ensemble shifts away from the closed state and that open-like states are present. We solve the structure in an expanded state by cryoEM, revealing an architecture with pore properties consistent with previous electrophysiology reports. By combining hydrogen-deuterium exchange mass spectrometry and molecular dynamics simulations, we investigate the dynamics of EcMscL gating in lipid bilayers, identifying sites involved in the closed-to-expanded transition. Combined, this enables us to inform on the elusive structural mechanism of EcMscL mechanosensitive channel function. Here, authors solve three cryo-EM structures of EcMscL in two different lipid environments and two distinct conformational states; closed and open-like, guided by EPR. Additional EPR, MD and HDX-MS experiments provide insight into the gating mechanism.
|
|
|
Scooped by
mhryu@live.com
August 23, 2:37 PM
|
In vitro reconstitution of protein systems─e.g., metabolic pathways, genetic circuits, or biosensors─often requires optimization to enhance their activity. Combinatorial DNA libraries that simultaneously target multiple genes allow for a holistic optimization strategy by studying the interplay between the systems’ components, which may reveal DNA variants that would be hidden when testing each element in isolation. Here, we screen large populations of synthetic vesicles that express combinatorial DNA variants of a DNA self-replicator or a phospholipid synthesis pathway. We simultaneously vary the strengths of multiple RBSs or synonymously mutate the first codons of multiple genes to explore the effects of the protein translation rates directly on the functionality of the two core synthetic cell modules. We isolated high performers through DNA self-selection or functional screening by fluorescence-activated cell sorting FACS. Long-read sequencing of the fittest variants revealed the optimal RBS strengths and base substitutions in the first codons and indicated which genes were most impactful in regulating the functionality of the protein systems. Single-mutation data were used to predict the fitness of combinatorial variants, which was compared with the experimental fitness observed. The theoretical fitness of combinatorial variants was extremely predictive for the two-gene library of the DNA replicator but less for the larger pathway library. Altogether, our approach exemplifies how combinatorial testing can be expanded from single proteins to multiprotein systems, which can in the future be extended to the evolutionary engineering of even larger genetic and metabolic networks, and eventually an entire artificial cell.
|
|
Scooped by
mhryu@live.com
August 23, 2:20 PM
|
Amplicon-based techniques provide a rapid and cost-effective approach for profiling microbial communities. However, the observed microbial diversity is influenced by a wide range of factors, encompassing pre-analytical steps such as the choice of primers and target regions, as well as the bioinformatic pipeline, including the selection of tools, reference databases, and parameter settings. Several benchmarks are already available in the literature, but the updates to important tools and databases, namely LotuS3, the Ribosomal Database Project and GreenGenes2, prompted our investigation. In this study, we conducted a comprehensive benchmark of the main bioinformatic tools and databases. Using seven regions for three publicly available mock communities of increasing complexity, we tested 38 possible combinations of sequence resolution algorithms (DADA2 stand-alone, LotuS3 (DADA2/UPARSE)), taxonomic classifiers and search tools (Kraken2, DECIPHER, RDP, MMseqs2, Lambda, and Metaxa2), and databases (SILVA, GreenGenes2, RDP, RefSeq, and Metaxa2). The region V1-V3, coupled with DADA2+MMseqs2+SILVA, DADA2+Metaxa2, or LotuS3 (DADA2)+RDP yielded the highest-quality estimates of the true diversity according to the metrics. We also demonstrated that even certain dominant genera remain difficult to detect, and that the quantification of all genera can be substantially over- or under-estimated, even when using optimal combinations of tools and reference databases.
|
|
Scooped by
mhryu@live.com
August 23, 2:03 PM
|
Barcoding methods are powerful tools for screening large libraries and have successfully been employed using DNA-centric approaches for over two decades. Yet despite the central role of proteins in most biological processes, protein-based barcoding methods have only recently emerged as a viable alternative. In this review we summarize recent advances in peptide barcoding and highlight its diverse applications, including screening of binding affinity, lipid nanoparticles, mRNA untranslated regions, and designed protein libraries. We discuss key challenges in barcode design, library construction, and mass spectrometry methods for accurate, scalable, and high-throughput screening. We propose that peptide barcoding represents a conceptual shift in genotype–phenotype mapping and will play an increasingly important role in AI-driven protein engineering, delivery technologies, and synthetic biology.
|
|
Scooped by
mhryu@live.com
August 22, 11:45 PM
|
DNA sequences derived from ancient samples provide insights into human history, paleoenvironments, and evolutionary biology. Advances in laboratory techniques and computational tools have established ancient DNA research as a distinct field. However, current analyses focus mainly on the DNA level, while the protein space remains under-explored. Recent progress in the de novo assembly of ancient metagenomes and the availability of protein structure prediction tools, such as AlphaFold 2, enable the reconstruction of protein structures from these degraded sequences. Here, we present a computational framework to assemble contigs, evaluate their authenticity as ancient sequences, predict open reading frames, and fold ancient protein structures directly from highly damaged metagenomic data. Applying this pipeline to two-million-year-old datasets from the Kap Kobenhavn Formation, we successfully rescued ancient proteins involved in methane metabolism. By generating structural models with AlphaFold 2 and comparing them to modern predicted reference structures, we demonstrate that these ancient proteins can be reconstructed and aligned with high confidence. We showcase this by analyzing an archaeal V/A-type ATP synthase protein recovered from the 2M-year-old Greenlandic data. Ultimately, our work proves that ancient proteins can be reliably recovered from highly degraded palaeogenomic material, establishing a new computational avenue for evolutionary and biochemical research.
|
|
Scooped by
mhryu@live.com
August 22, 11:22 PM
|
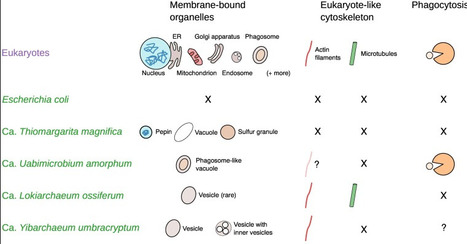
Cellular organisms can be divided into two basic types of cells: the prokaryotic cells of Bacteria and Archaea and the eukaryotic cells. The rapidly expanding knowledge of the diversity and ultrastructure of prokaryotic cells has revealed cellular intricacies that warrant a critical reappraisal of the profundity of the prokaryote–eukaryote divide.
|
|
Scooped by
mhryu@live.com
August 22, 11:13 PM
|
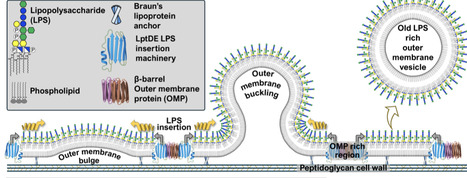
The Gram-negative outer membrane is a load-bearing permeability barrier dependent on ordered lipopolysaccharide (LPS) packing in its outer leaflet. How this organization is maintained after LPS insertion, and whether bacteria can remodel LPS independently of growth, remain unclear. Existing models attribute LPS turnover to passive dilution during elongation and division, limiting adaptation as growth slows. Here we show that, as E. coli enters stationary phase and elongation slows, new LPS insertion continues while pre-existing LPS is preferentially removed through outer membrane vesicles, enabling growth-independent surface remodelling. Pulse–chase metabolic labelling and super-resolution microscopy reveal that newly inserted LPS localizes to discrete sites and remains segregated from pre-existing LPS. Spatiotemporal analysis supports an insertion-trapping model in which localized insertion and restricted lateral diffusion maintain LPS-rich patches without coarsening into larger domains. Time-lapse imaging, biochemical fractionation and nanoparticle tracking identify vesicle release as a route that uncouples LPS turnover from cell growth. Lipopolysaccharide (LPS) organization and turnover in E. coli is integral to outer membrane homeostasis. Here, pulse-chase labelling and imaging reveal sustained spatial segregation of pre-existing and newly inserted LPS, together with growth-independent LPS turnover by vesiculation.
|
|
Scooped by
mhryu@live.com
August 22, 10:40 PM
|
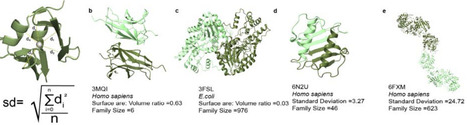
A fundamental question in structural biology centres around understanding protein evolution. Key to this process is mutational robustness, defined as the protein fold's ability to absorb sequence changes without collapsing its structure. Here, we show that robustness is systematically shaped by simple features such as protein size, geometry, and oligomeric state. We used Foldseek-identified (structural) homologs to quantify family size across monomers and higher homo-oligomers. We found that proteins in larger families are consistently larger in size, more compact in atomic density, and less exposed to solvent. Strikingly, homo-oligomers occupy systematically larger families than monomers, revealing quaternary structure itself as a driver of mutational tolerance, not merely a functional supplement. This signature of robustness can be further linked to increasing functional complexity in proteins; those with adaptive, multifaceted biological roles belong to larger structural families than those with specific roles, thereby linking structural flexibility directly to evolutionary versatility. In short, simple yet overlooked features of protein geometry can explain mutational robustness and evolvability, offering a structural rationale for why certain protein families have diversified extensively while others remain in evolutionary stasis.
|
|
Scooped by
mhryu@live.com
August 22, 10:20 PM
|
Rift Valley Fever Virus (RVFV) is a mosquito-borne zoonotic pathogen responsible for severe disease in domestic and wild ungulates as well as humans, representing a major threat to livestock production and human public health. RVFV is endemic in many African countries and has the potential to spread to new geographical regions. Current vaccines have limitations in safety and efficacy, highlighting the need for strategies to develop new vaccines candidates. In this study, we explored the use of codon deoptimization (CD) as a novel attenuation approach for the development of live-attenuated vaccine (LAV) against RVFV. CD exploits the redundancy of the genetic code by replacing frequently used codons with synonymous, less-preferred codons, thereby reducing translational efficiency without altering the amino acid sequence. We recoded parts of the M and S genome segments of RVFV using the least frequently used codons in mammalian cells, ensuring complete preservation of protein functionality and immunogenicity. Using reverse genetics, we rescued a panel of recombinant (r)RVFV encoding codon-deoptimized S-segment NSs gene (rNScd), M-segment Gn/Gc genes (rMcd), or both (rMcd/NScd). These recombinant CD viruses were characterized in vitro in mammalian and insect cell lines and in vivo using wild-type and immunocompromised mice. Results demonstrated varying degrees of attenuation among the three CD rRVFV, with the one deoptimized in both viral segments, rMcd/NScd, as a promising LAV based on the safety profiles. This study provides proof of concept for the use of CD as a rational strategy to generate attenuated RVFV, for the development of next-generation vaccines against this zoonotic threat.
|
|
Scooped by
mhryu@live.com
August 22, 4:27 PM
|
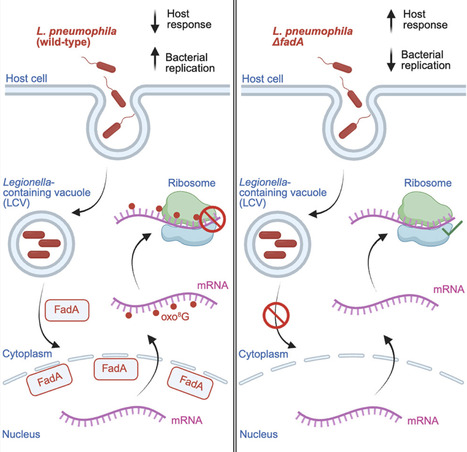
Bacterial pathogens harbor specialized secretion systems that inject effector proteins into the host cell to establish infection and disease. While many bacterial effectors post-translationally modify proteins to influence host responses, the extent to which effectors modify host RNA is currently unknown. Here we performed RNA-interactome capture (RIC) to isolate effectors bound to host cellular messenger RNA (mRNA) during Legionella pneumophila infection. RIC identified an uncharacterized effector, FadA (Lpw16921), which localized to the host-cell nucleus and interacted with host mRNAs at uracil (U)-rich RNA motifs. FadA exhibited NADPH-oxidase activity that mediated 8-oxo-guanine (oxo8G) modifications of mRNA substrates, resulting in oxidative damage and inhibition of translation. Infection with L. pneumophila harboring wild-type FadA, but not a catalytically inactive mutant, increased oxo8G modifications, suppressed cytokine responses, and promoted bacterial persistence in vivo. Our findings demonstrate the potential for a secreted effector to post-transcriptionally modify host mRNA as a mechanism to promote bacterial virulence.
|
|
Scooped by
mhryu@live.com
August 22, 4:09 PM
|
Programmed −1 ribosomal frameshifting (PRF) is a translational control mechanism used by RNA viruses to regulate the relative abundance of proteins encoded in different reading frames. Cardioviruses exhibit the highest known PRF efficiency, with ∼85% of ribosomes shifting into the −1 frame. This unusual event requires an interaction between the viral 2A protein and a stimulatory element in the RNA genome, but the basis for protein dependence is unclear. To address this, here we investigate the structure and dynamics of the PRF signal in Theiler’s murine encephalitis virus (TMEV). By combining X-ray crystallography, small-angle X-ray scattering (SAXS), and single-molecule fluorescence resonance energy transfer (smFRET), we show that 2A binding switches the RNA from a stem-loop conformation into a pseudoknot, and we demonstrate that pseudoknot formation is essential for efficient PRF in vitro and in cells. Together, these findings illustrate how the cardiovirus PRF element behaves as a protein-dependent riboswitch, defining the molecular mechanism by which frameshifting is conditionally activated.
|
|
Scooped by
mhryu@live.com
August 22, 1:58 PM
|
The application repertoire of industrial biotechnology is constrained by the reaction scope of natural biocatalysis, which covers only a fraction of the accessible chemical space. To expand the versatility of biomanufacturing, abiological organometallic catalysts can be integrated into synthetic biology in the form of artificial metalloenzymes (ArMs). ArMs have been developed for a broad range of new-to-nature reactions, and in recent years multiple examples of their successful implementation in vivo have been demonstrated. Nevertheless, whole-cell ArM catalysis remains at the stage of fundamental research, and hybrid metabolic systems incorporating ArMs have yet to be realized at scale. In this review, we summarize the recent advances in whole-cell ArM catalysis and outline the challenges associated with in vivo ArM incorporation. We highlight the additional complexity that arises when transitioning from simple whole-cell biotransformations to metabolic engineering with ArMs and discuss potential strategies to achieve efficient integration of ArMs into biosynthetic pathways.
|
|
Scooped by
mhryu@live.com
August 22, 1:34 PM
|
Recent advances in computational methods for designing biological sequences have sparked the development of metrics to evaluate these methods performance in terms of the fidelity of the designed sequences to a target distribution and their attainment of desired properties. However, a software library implementing these metrics was lacking. In this work we introduce seqme, a modular and highly extendable open-source Python library, containing model-agnostic metrics for evaluating computational methods for biological sequence design. seqme considers three groups of metrics: sequence-based, embedding-based, and property-based, and is applicable to a wide range of biological sequences: small molecules, DNA, ncRNA, mRNA, peptides and proteins. The library offers a number of embedding and property models for biological sequences, as well as diagnostics and visualization functions to inspect the results. seqme can be used to evaluate both one-shot generation and iterative optimization. We show the utility of seqme by performing an antimicrobial peptide benchmark and acquiring mRNA data.
|












2st, used 209 single-point mutations with measured activity to train the BLOSUM62-kernel GPR