 Your new post is loading...

|
Scooped by
mhryu@live.com
September 25, 2:08 PM
|
Genes function within dense networks of interactions, where phenotypes often depend on the relative expression levels rather than loss or gain of function. Most genetic interactions in Saccharomyces cerevisiae have been identified using deletions or overexpression, leaving dosage-dependent interactions underexplored. Progress in this area requires transcriptional control systems that enable simultaneous, precise regulation of multiple genes with minimal cross-talk. Here, we expand the recently developed Well-tempered Controller (WTC846), a TetR-repressible system that provides precise, graded control of gene expression in response to anhydrotetracycline. We extend this framework to two orthogonal repressor-inducer pairs: LexA-hER/β-estradiol and LacI/IPTG, establishing three compatible transcriptional controllers. We demonstrate robust, tunable regulation of endogenous genes spanning low to high expression levels. We achieve simultaneous, graded, and precise double and triple gene control, validating known dosage-dependent interactions within the anaphase signaling network and uncovering additional phenotypes. These orthogonal controllers provide a versatile toolkit for dissecting dosage-sensitive gene-gene interactions and facilitate systematic exploration of complex genetic networks in yeast.
|
|
Scooped by
mhryu@live.com
September 25, 1:34 AM
|
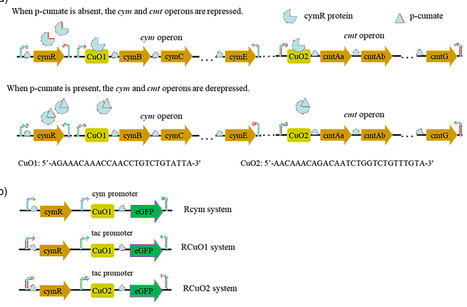
In this study, we developed two novel cumate-inducible expression systems by engineering distinct cumate-responsive operators, CuO1 and CuO2, respectively derived from the cym and cmt operons in P. putida KT2440. We assessed the expression strength of the constructed systems and optimized inducer concentrations using eGFP fluorescence intensity as a reporter. Through systematic promoter optimization, operator architecture optimization, and quantitative benchmarking, we achieved substantial improvements in system performance. Finally, we applied the optimized system to bio-transform limonene into perillyl alcohol via a heterologous cytochrome P450 to achieve an increase in the production. Cumate-inducible expression system R2CuO1 demonstrated superior gene expression strength than the IPTG-inducible system Ilac. We successfully implemented our optimized cumate-responsive platform for perillyl alcohol bio-production from limonene, achieving a titer of 40.93 mg·L⁻¹, 2.1 times higher than that of the conventional lac expression system.
|
|
Scooped by
mhryu@live.com
September 25, 1:14 AM
|
Ribosome hibernation is a conserved bacterial stress-response mechanism that promotes translational shutdown and enhances survival under adverse conditions, contributing to persistence and tolerance to ribosome-targeting antibiotics. Here, we report high-resolution cryo-electron microscopy (cryo-EM) structures (2.5–2.8 Å) of hibernating 70S ribosomes from four clinically important ESKAPE pathogens: Pseudomonas aeruginosa, Enterobacter hormaechei, Klebsiella quasipneumoniae, and Acinetobacter baumannii. Structural analyses identified the bound hibernation factors as HPF in P. aeruginosa and E. hormaechei, and YfiA in K. quasipneumoniae and A. baumannii. Despite sequence divergence, HPF and YfiA adopt a conserved fold and occupy the same ribosomal binding site, interacting primarily with 16S rRNA and ribosomal proteins uS7 and uS9 and occupying the A- and P-sites while extending toward the E-site. Comparative analyses revealed a conserved core interaction network, including contacts with functionally important modified 16S rRNA nucleotides, alongside species-specific adaptations that preserve overall ribosome-binding architecture. Analysis of hibernating ribosome populations uncovered substantial heterogeneity in E-site tRNA occupancy, bS21 association, and mRNA binding among species, suggesting that these features are species-dependent rather than determined solely by the identity of the hibernation factor. Together, these structures provide a comprehensive comparative view of HPF- and YfiA-mediated ribosome hibernation across major Gram-negative pathogens, revealing conserved molecular principles and species-specific adaptations that expand our understanding of bacterial translational dormancy and establish a structural framework for future antibacterial strategies targeting ribosome hibernation. Cryo-EM structures of hibernating ribosomes from four Gram-negative pathogens reveal HPF/YfiA-mediated translation inhibition and species-specific features.
|
|
Scooped by
mhryu@live.com
September 25, 12:59 AM
|
The history of cheesemaking is deeply intertwined with the evolution of microbial communities, from spontaneous fermentation to modern, standardized practices. The rapid technological changes of the last century likely induced profound alterations in cheese microbial communities, yet this remains largely underexplored. Using shotgun metagenomics and 16S rRNA amplicon sequencing, we examined microbial community changes in Raclette du Valais, a traditional Swiss cheese, using preserved wheels from 1875 to 2017 from the same Alpine dairy. Our results reveal that significant differences in microbial community composition coincide with changes in production practices. The oldest cheese harbored a distinct bacterial community, dominated by Lactiplantibacillus paraplantarum, Streptococcus thermophilus, Pseudolactococcus laudensis, and gut-associated taxa. Antibiotic-resistance genes mirrored historical antibiotic use, lactic acid bacteria domestication predated the studied period, and bacteriophage genera from 1875 were already comparable to those of modern cheese factories. These findings highlight how human practices have shaped cheese microbiomes over time.
|
|
Scooped by
mhryu@live.com
September 25, 12:53 AM
|
Functional redundancy is a key biological concept that offers critical insights into microbial ecosystem stability and responses to environmental perturbations. Existing methods to quantify redundancy typically rely on gene annotations as functional units, limiting their ability to capture complex or partially characterised traits and making analyses from metagenomic data—often fragmented or incomplete—challenging. Here, we present miFRED (microbial Functional REDundancy), an accessible computational approach to quantify functional redundancy of microbial phenotypes and communities based on phenotypic rather than genetic annotations. Leveraging 86 machine-learning-predicted phenotypes as functional units, miFRED bridges the genotype–phenotype gap and enables interpretable and accurate assessment of redundancy at both community and single phenotype levels, as demonstrated on simulated communities. As case studies, miFRED was applied to over 300 metagenomic samples from anaerobic systems, to a longitudinal dataset of a gut microbiome subject to antibiotic treatment and 100 marine and soil metagenomes. Across these applications, miFRED elucidated relationships between redundancy, community structure and functional organisation. Comparison to gene annotation-based analyses highlighted the improved interpretability of phenotype-based redundancy estimates, which allowed clearer resolution of functional changes associated with microbiome perturbation and recovery in the human gut dataset. In anaerobic digestion communities, analyses considering environmental conditions uncovered changes in redundancy, complexity and functional profiles with rising temperatures, with more extreme conditions favouring simpler, more redundant communities and shifts in redundant functions. Using phenotype-based functional units, miFRED provides a practical and general framework for consistent functional redundancy analyses across environments and metagenomic datasets. By interpreting redundancy patterns in the context of community organisation and environmental factors, it enables exploration of microbial functional landscapes across environmental conditions in both natural and engineered ecosystems.
|
|
Scooped by
mhryu@live.com
September 25, 12:35 AM
|
Förster resonance energy transfer (FRET) is commonly used to monitor protein-protein interactions in situ. The high spatiotemporal resolution and facile implementation inside complex molecular environments have spearheaded FRET's widespread adoption in biosensing. Despite these advantages, current FRET biosensors are largely restricted to the detection of the presence/absence of individual inputs and are thus unable to sense several multiplexable inputs simultaneously within complex milieu of biological environments. In this work, we introduce a generalizable strategy to construct genetically encoded protein-based FRET biosensors capable of recognizing multiple inputs following Boolean logic-type (YES/OR/AND) operations. These topologically specified FRET sensors powerfully expand the input capacity in sensing protein-protein interactions while providing a user-programmable platform for monitoring heterogeneous biological activities both in vitro and in living cells.
|
|
Scooped by
mhryu@live.com
September 25, 12:24 AM
|
Bacterial cultures entering stationary phase (SP) undergo complex physiological alterations, helping the cells to survive when medium resources are exhausted. The onset of various stress responses underlying SP physiology is generally believed to be due to reactions of individual cells to the environmental cues such as starvation, toxic metabolites, etc. The SP physiological state makes bacteria unsuitable for the replication of most bacteriophages; however, some phages are able to infect and multiply in them. We investigated E, coli phage DH23 growth in SP cultures of E. coli MG1655 infected at different hours post inoculation (ages). Under our conditions the cells enter SP at about 6 h, but the phage replication was possible till 11h and then dropped abruptly by 13h of culture aging, indicating an abrupt physiological change to deeper dormancy during SP. The onset of this phage-inhibiting middle-SP dormancy (MSPD) turned out to be mediated by intercellular communication mediated by the middle-SP signal particles (MSP) which are larger than 100 kDa and contain both RNA and DNA. These MSP are inactivated by RNAse or by DNAse, enabling phage growth in 14h-old cultures and lifts the tolerance of such cultures to kanamycin. Moreover, the RNAse or DNAse treatment makes 24h culture spent media suitable for additional cell growth, and cultures initiated in fresh LB supplemented with RNAse reach an OD600 about 1.5 times higher compared to the untreated control. This indicates that MSP signaling influences cell physiology well before the MSPD onset and helps the population cease growth pre-emptively to save about 1/3 of medium resources to support the viability during SP.
|
|
Scooped by
mhryu@live.com
September 24, 11:39 PM
|
Accurate and fast prediction of protein binding sites remains essential for understanding molecular interactions and facilitating protein engineering. Here, we present SurfGraphPro, a geometric deep learning approach that bridges protein language models with surface-based structural representations for a rapid binding interface prediction. Our method operates on coarse-graphed triangulated protein surfaces, utilizing solvent-excluded surface meshes downsampled into amino acid residue centered patches. Unlike existing approaches that rely on extensive physicochemical feature engineering, we leverage evolutionary information directly from protein language model embeddings, eliminating the need for computationally expensive multiple sequence alignments and hand-crafted features. This integration achieves on average 18-28 times speedup for proteins of 100 to a few 1000s of amino acids over current state-of-the-art surface-based model while maintaining comparable accuracy on diverse binding interfaces, including challenging antibody-antigen complexes. To our knowledge, this represents the first approach to integrate protein language model embeddings with coarse geometric surface representations for binding site prediction, demonstrating that learned evolutionary features coupled with geometric transformers can replace traditional feature engineering without sacrificing performance.
|
|
Scooped by
mhryu@live.com
September 24, 11:23 PM
|
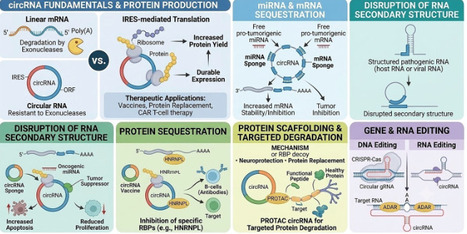
Circular RNAs (circRNAs) have emerged as a promising class of therapeutic molecules distinguished by their covalently closed topology, which provides exceptional exonuclease resistance, prolonged intracellular stability, and sustained protein expression. These properties, combined with reduced innate immunogenicity and capacity for cap-independent translation, position circRNAs as attractive candidates for vaccines, oncology therapeutics, and treatments for genetic and neurological disorders. Parallel advances in chemical biology have significantly expanded the synthetic toolkit for generating circRNAs, complementing traditional enzymatic ligation and ribozyme-based approaches with efficient chemical, chemoenzymatic, and bioorthogonal circularization strategies that enable scalable production and incorporation of diverse chemical modifications. This review integrates the biological roles of circRNAs with a comparative analysis of emerging synthetic methods, highlighting their mechanistic principles, advantages, and limitations. Advances in delivery platforms and multi-omics validation further strengthen the translational potential of engineered circRNAs as next-generation RNA therapeutics.
|
|
Scooped by
mhryu@live.com
September 24, 10:57 PM
|
Reliable constitutive promoters for non-model bacteria are lacking, resulting in a bottleneck for genetic tool development. Existing computational promoter predictors are trained on model Gammaproteobacteria and degrade on phylogenetically distant or compositionally atypical genomes. Here we present ProFinder, a computational method that integrates three biologically informed criteria for promoter prediction: a conserved 98-gene constitutive marker panel, an empirically derived intergenic search window, and a 72-motif σ70 motif catalogue built from diverse lineages. From an input bacterial assembly, ProFinder returns a ranked shortlist of putative constitutive promoters. It matches the precision of full-genome classifiers and is more robust to GC extremes. Applied to 56,742 bacterial genomes spanning 149 phyla, ProFinder returned candidate promoters for 99.76%, delivering a pan-bacterial catalogue of pre-computed constitutive promoter parts to accelerate chassis development across the bacterial tree. https://plabase.cs.uni-tuebingen.de/profinder/
|
|
Scooped by
mhryu@live.com
September 24, 4:34 PM
|
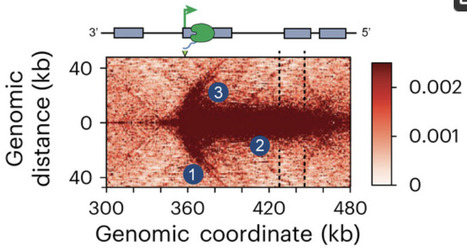
Recent high-resolution (≈500 bp) Hi-C experiments reported contact maps with unusual patterns around highly expressed bacterial DNA loci. These patterns, described as “arched stripes” and “bundled domains”, extend over nearly 100 kbp. We performed Brownian Dynamics simulations with a specially designed coarse-grained model to rationalize these findings. The main feature of the model is that it takes explicitly into account the waves of positive (respectively, negative) supercoiling generated by the translocating polymerase downstream (respectively, upstream) of its position. Contact maps computed from the simulations also display the arched stripe and bundled domain patterns for above-threshold values of the rate of twist injection. Computed DNA conformations indicate that these patterns reflect an extraordinarily entangled DNA geometry, which involves both plectonemic and toroidal supercoiling, with some DNA segments experiencing both of them simultaneously. Moreover, DNA segments located on each side of the polymerase systematically wind around tracts located on the other side, which is a purely out-of-equilibrium effect driven by the continuous injection of twist. The present work therefore reveals that repeated transcription of a DNA locus systematically brings into contact DNA segments separated by several tens of kbp, which may eventually contribute to allosteric modulation and long-range communication.
|
|
Scooped by
mhryu@live.com
September 24, 3:42 PM
|
Despite the significant progress made in recent years, current AI-driven protein engineering methods often suffer from iterative experimental validation, limited success rates, modest improvements, and/or high computational costs. Moreover, their utility for evolving plant proteins remains unexplored. Here we present unZipro, an efficient, scalable, and generalizable framework for zero-shot, in silico protein evolution. unZipro integrates a compact, pre-trained inverse folding model with meta-learning to derive family-specific fitness landscapes. We demonstrate unZipro’s ability to directly identify high-activity variants from minimal libraries (∼10 candidates) with an average success rate of 61% across nine diverse proteins, achieving up to a 28-fold increase in the gene-editing activity of T5E-CasΦ2 fusion variants. Leveraging unZipro, we developed state-of-the-art plant gene-editing nucleases, superior firefly luciferase variants, enhanced rice transcription factors, and barley-derived antiviral proteins with elevated potency. Overall, unZipro represents a new paradigm for cost-effective, widely accessible, and transformative protein engineering in biology, biotechnology, and agriculture.
|
|
Scooped by
mhryu@live.com
September 24, 12:12 PM
|
TnpB nucleases, the evolutionary progenitors of CRISPR-associated Cas12 enzymes, are transposon-encoded, RNA-guided endonucleases found throughout bacteria. Independent of the trajectory towards adaptive immunity, TnpB nucleases have also recurrently given rise to TnpB-like nuclease-dead repressors (TldRs), a family of programmable RNA-guided transcription factors, though the physiological roles of most TldR clades remain unclear. Recently, we identified a TldR clade associated with bacterial ABC transporter operons, but this clade has not been characterized in any native host, leaving the biological significance of its predicted regulatory function unknown. Here, we demonstrate direct in vivo repression of the oligopeptide permease (opp) binding protein OppA in Enterococcus faecalis, implicating TldR in shaping the substrate repertoire of bacterial peptide import machinery. Phylogenetic and comparative genomic analyses reveal that bacterial genomes typically encode multiple, structurally conserved but functionally diversified OppA paralogs, suggesting that TldR-mediated repression could enable selective tuning of transporter composition. To define the structural basis of this regulatory specificity, we used cryo–electron microscopy to capture an oppF-associated TldR in multiple functional states, revealing a conserved bilobed architecture and a TAM recognition mechanism inherited from TnpB ancestors. Together, these findings define the structural, genetic, and evolutionary basis of a widespread RNA-guided regulatory system domesticated from mobile genetic elements to tune peptide transport in bacteria.
|
|
|
Scooped by
mhryu@live.com
September 25, 2:02 PM
|
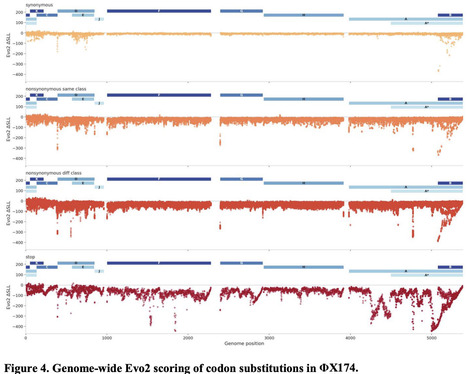
Reliable biological prediction by AI is most likely to emerge first in the simplest systems with rich datasets and the fastest opportunities for testing and refinement. Phages with small genomes are an ideal testbed. Decades of experimental work have created an unusually information-rich literature benchmark that sits largely outside the sequence repositories typically used to train genome language models (GLMs). Recent work has shown that GLMs such as Evo2 can generate viable whole bacteriophage genomes, demonstrating that genome-scale biological design is possible. The next question is more mechanistic: can such models correctly predict the effects of simple, local sequence changes? Here, we evaluated Evo2 against experimental mutation data from two model phages: the single-stranded RNA phage MS2 and the single-stranded DNA phage ΦX174. We first addressed whether Evo2 sequence log-likelihood scores could distinguish viable from nonviable mutations, and then whether models trained on Evo2 embeddings were predictive of function. Across both phages, Evo2 captured expected sequence-level constraints: stop codons were generally penalized, synonymous substitutions had higher likelihood than nonsynonymous substitutions. Evo2 distinguished among synonymous codons in ways only weakly explained by host codon usage. However, for MS2, these capabilities did not translate into robust biological predictions. Specifically, Evo2 ΔSLL failed to distinguish functional from nonfunctional mutations in the lysis gene, an overlapping viral region that appears to be a particularly hard test case. In ΦX174, performance was stronger but still modest, and much of the apparent signal could be explained by simple covariates such as nonsense mutations, genomic position, and nucleotide distance from the reference. Together, these results introduce phages as a tractable proving ground for stress-testing GLMs against experimentally grounded genotype-to-phenotype tasks. More broadly, they provide a durable framework for identifying what data and model ingredients are required for biologically reliable prediction.
|
|
Scooped by
mhryu@live.com
September 25, 1:15 AM
|
Fungal bio-leaching, as a green and sustainable technology for metal recovery, demonstrates unique advantages in addressing growing global metal demand and utilizing secondary resources. This review systematically summarizes recent progress and technological advances in fungal bioleaching for metal recovery. Fungi solubilize metals through three core mechanisms, acidolysis, complexolysis, and redoxolysis, mediated by organic acids (citric, oxalic, gluconic), while cell wall functional groups enable biosorption. Most frequently used genera in modern bioleaching (Aspergillus, Penicillium, Trichoderma) have achieved remarkable recoveries from e-waste (Cu, Li, Co up to 100%), rare earth elements (consortia up to 76%), tailings, and spent catalysts. Optimization of key parameters (pH, temperature, pulp density) and application of intelligent strategies (response surface methodology, machine learning) have further enhanced leaching efficiency. Strain engineering and synthetic biology offer new avenues for constructing hyper-efficient strains. Despite remaining bottlenecks such as slow kinetics and scale-up difficulties, fungal bioleaching holds broad industrial prospects for advancing the circular metal economy and the green metallurgical transition.
|
|
Scooped by
mhryu@live.com
September 25, 1:06 AM
|
Current recycling technologies address less than 10% of global plastic waste, necessitating alternative valorization routes. Biological upcycling via enzymatic depolymerization combined with microbial conversion of the resulting monomers offers a promising pathway to transform mixed-plastic waste into valuable alternatives. In this research article, we employed a single engineered Pseudomonas putida KT2440 for simultaneous co-utilization of five plastic monomers including ethylene glycol, terephthalate, adipate, 1,4-butanediol, and l-lactic acid, which can be derived from enzymatic hydrolysis of polyethylene terephthalate (PET), poly(butylene adipate-co-terephthalate) (PBAT), polyester polyurethanes (PUs), and polylactic acid. Continuous fermentation over 21 days with alternating mixed-monomer feeds achieved steady-state growth and complete substrate depletion, yielding adaptive mutations that informed iterative strain improvement. Further engineering enabled the biosynthesis of (R)-3-hydroxybutyrate (R-3HB), and 0.70 g l−1 R-3HB was produced directly from enzymatic hydrolysates of blended PET, PBAT, and thermoplastic PU. These results establish a viable bio-based approach for upcycling realistic mixed plastics into value-added bioproducts.
|
|
Scooped by
mhryu@live.com
September 25, 12:57 AM
|
Plasmids are central drivers of antimicrobial resistance (AMR) dissemination, yet their modular, recombinogenic genomes defy concepts of relatedness derived from bacterial chromosomes. Long-read sequencing now routinely yields complete plasmid sequences, exposing a key gap: we can reconstruct plasmids but lack agreed principles for comparing them. In response, diverse clustering tools have emerged that emphasise different signals, such as marker genes, whole-sequence similarity, gene content, backbone structure, or explicit rearrangement events. Each encodes a distinct notion of plasmid distance. This review organises these tools into conceptual families, highlights how their assumptions shape surveillance outputs, and proposes hierarchical, multitool strategies and clearer models of plasmid evolution as the basis for scalable and interpretable plasmid-based AMR surveillance.
|
|
Scooped by
mhryu@live.com
September 25, 12:48 AM
|
Glucoamylase is essential for industrial starch saccharification, but the limited thermostability and near-neutral pH tolerance of fungal glucoamylases necessitate cooling and acidification of liquefied starch. Here, we developed an artificial intelligence-guided strategy to simultaneously improve the thermostability, pH tolerance, and catalytic activity of glucoamylase from Penicillium oxalicum (PoGA). Two property-specific machine-learning models, CASPE-T and CASPE-A, identified substitutions associated with thermostability and pH tolerance, respectively. Experimental screening identified beneficial substitutions in 11 of 21 CASPE-T and 12 of 22 CASPE-A candidates. Folding-energy-guided recombination integrated the two traits while maintaining structural compatibility. The optimal variant, PoGA T513E/Q305N, exhibited 2.21-fold higher specific activity than the wild type, with half-life extended from 22.3 to 57.9 min at 60 degrees C and from 16.6 to 64.7 min at pH 8.0. Molecular dynamics simulations attributed these improvements to reinforcement of high-occupancy hydrogen-bonding networks, suppression of conformational fluctuations in the linker and carbohydrate-binding module, enhanced long-range dynamic coordination, and preservation of a compact catalytic architecture. At 60 degrees C and pH 6.5 without acidification, PoGA T513E/Q305N produced 219.9 g/L glucose and achieved 89.1% starch conversion, 31.4% higher than the wild type. This work provides an efficient framework for multi-objective enzyme engineering and sustainable starch biorefining.
|
|
Scooped by
mhryu@live.com
September 25, 12:30 AM
|
Recent advances in deep learning-based structure prediction, including AlphaFold3 and the open-source Boltz model family, have extended biomolecular modeling to joint prediction of protein-ligand, protein-nucleic acid, and multi-chain complexes with binding-affinity estimation. Boltz-2 is among the most feature-complete of these open models, but its practical use requires a local CUDA-capable GPU, command-line execution, and manually authored YAML configuration files, limiting accessibility for researchers without dedicated computational infrastructure. We developed Boltz2-Notebook, a Colab-native interface comprising four integrated stages - automated environment setup, interactive parameter-to-YAML generation, execution management, and automated confidence and affinity visualization - together with a manifest-driven batch mode for multi-target screening. All modelling capabilities are inherited unmodified from Boltz-2; Boltz2-Notebook's contributions are limited to accessibility, input construction, and workflow automation. Independent of the software, we curated a benchmark of 317 protein-ligand pairs (122 proteins, 277 ligands) from BindingDB and predicted binding affinity in triplicate using the Boltz-2 command-line engine on high-performance computing infrastructure. Predicted and experimental pIC50 values showed moderate correlation (Pearson r = 0.609 [95% CI 0.540-0.675]; Spearman ρ = 0.625; R2 = 0.371; MAE = 0.968 pIC50 units), with high triplicate reproducibility (pairwise r = 0.97) but a systematic compression of the predicted affinity range and no measurable relationship between Boltz-2's self-reported confidence metrics and prediction accuracy. Boltz2-Notebook is freely available as open-source software and provides external, reproducible evidence - including a specific confidence-calibration limitation - relevant to interpreting Boltz-2 affinity predictions responsibly.
|
|
Scooped by
mhryu@live.com
September 25, 12:21 AM
|
Plasmid construction underpins molecular biology and synthetic biology, yet validation is often limited to the inserted fragment rather than the whole plasmid, and around a third of laboratory-made plasmids carry sequence errors that can affect function. Sanger sequencing scales poorly across whole plasmids, while short-read approaches cannot resolve the repeated DNA parts, such as promoters, that are common in synthetic constructs. We present PICARD-seq, a rapid nanopore-based protocol that uses off-the-shelf Tn5 rapid barcoding reagents and a MinION to sequence pools of whole plasmids in under a day, and we systematically benchmark the computational pipelines available for analysing the resulting data. Using a curated set of 25 plasmids of known sequence spanning 3.0-20.6 kbp, including various dilution series and repetitive multi-part constructs, we ran five independent replicates of each pipeline. The ONT EPI2ME Clone Validation workflow was fast (13-18 min) but stochastic, varying between replicates for both plasmids assembled and what sequence was returned; Canu outperformed the default Flye assembler, and reducing the minimum coverage parameter from 60x to 20x substantially improved assembly of large, repetitive, and dilute samples. The ensemble assembler Autocycler was slower (81-111 min) but gave the highest and most consistent rate of recovering the expected sequence. Complementary read mapping with minimap2 distinguished genuine sequence differences from assembly artefacts. Applying PICARD-seq to problematic plasmids revealed backbone concatemers, a misincorporated promoter part, and a mixed population of rearranged molecules in a repetitive construct. PICARD-seq makes routine whole-plasmid validation practical and affordable for individual laboratories.
|
|
Scooped by
mhryu@live.com
September 24, 11:36 PM
|
CRISPR/Cas technology has been transformative for genome editing, enabling the precise integration of large DNA fragments—a capability essential for advanced genome (re)writing in plants, such as for trait stacking and pathway engineering. However, several new RNA-guided systems derived from transposable elements (TEs) have shown promise for plant genome editing, thereby enriching the toolkit available for plant engineering. This review comprehensively analyzes these emerging TE-based editors, including OMEGA nucleases (TnpB, IscB, Fanzor), CRISPR-associated transposases (CASTs), and R2 retrotransposon–derived systems. We detail their distinct architectures, evolutionary origins, and unique advantages over traditional Cas9, such as their compact size, simplified guide RNAs, and staggered DNA cleavage. We critically evaluate their nascent applications in plant models, highlighting ongoing challenges in editing efficiency, delivery, and specificity. Notably, CASTs and R2 retrotransposon–derived systems show particular promise for programmable large-fragment DNA integration, offering potential solutions for next-generation plant genome writing applications. We also examine the critical link between genome editing and plant regeneration, discussing phytohormonal and morphogenic regulators (e.g., BBM, WUS), and innovative tissue-culture-free methods, such as Cut-Dip-Budding. By comparing their merits and limitations, we position these systems not as replacements but as complementary tools within an expanding genome-editing toolkit. Integrating optimized TE-based editors with robust regeneration strategies is poised to unlock new frontiers in plant synthetic biology and crop improvement.
|
|
Scooped by
mhryu@live.com
September 24, 11:21 PM
|
Division of labor is commonly associated with cooperative behavior, yet one of its most extreme forms occurs during bacterial warfare, where a subset of cells undergoes suicidal lysis to release toxins. Why bacteria divide labor among a few cells rather than producing toxin uniformly remains unknown. Here, we combine timelapse microscopy and simulations, to understand the division of labor during bacterial warfare using bacteriocin (colicin) production by the gut bacterium E. coli as a model system. At the single-cell level, we find that lytic toxin production is a tightly regulated event: only cells that commit to lysis produce significant toxin and then lysis only occurs once a large amount of toxin has been made. This high threshold ensures each sacrifice delivers a large dose, which is released in a rapid burst from a lysing cell. While such burst-like release appears to provide no advantage over uniform labor in well-mixed conditions, we show it becomes extremely effective in spatially structured populations where the rapid release of toxin by one cell can generate lethal concentrations locally and eliminate competitors. Finally, we explain why the lysing fraction remains so small. While an increase in the producing cells increases toxin levels, it also increases the probability of local patch extinctions. The division of labor during bacterial warfare, therefore, enables powerful localized killing while safeguarding the population from self-destruction.
|
|
Scooped by
mhryu@live.com
September 24, 10:44 PM
|
Microbial metabolism in extreme environments has long been shrouded in profound mystery. Distinct from the direct assimilation of exogenous organic carbon, microorganisms predominantly exploit inorganic nitrogen substrates as their primary nitrogen sources. As a critical nitrogen assimilation pathway, assimilatory nitrite reduction plays a vital role in microbial nitrogen acquisition, especially in extreme environments with poor nutrient availability. In this study, we identified the coexistence of two isoforms of NADH-dependent nitrite reductase in single genomes. NIR-α and NIR-β, named based on their phylogenetic relationships, exhibit significant differences in protein sequence, genomic context and evolutionary relationship, a phenomenon that has rarely been reported before. They also show distinct expression patterns, which may allow bacteria to achieve efficient nitrogen conversion in nutrient-poor environments. This finding calls for a revision of the conventional model of nitrogen cycling gene combinations inferred from common model microorganisms and holds numerous implications for how we understand and study the environmental adaptation mechanisms of extremophiles.
|
|
Scooped by
mhryu@live.com
September 24, 4:18 PM
|
Proximity labeling (PL) proteomics, primarily powered by engineered biotin ligases such as BioID and TurboID, has emerged as a transformative approach for mapping protein association networks and subcellular proteomes in living cells. By covalently biotinylating proteins within a nanometer-scale radius of a bait protein, PL captures transient, weak, and spatially restricted associations that often escape conventional affinity-based methods. However, applying PL in plants introduces distinctive challenges, including rigid cell walls that can limit biotin penetration, tissue-specific variation in substrate accessibility, enzyme temperature sensitivity, and the difficulty of removing excess free biotin after labeling. Here, we outline best practices for designing and implementing biotin ligase-based PL experiments in plant systems, drawing on experience across multiple species. We discuss key considerations, including enzyme selection, expression system design, fusion protein validation, biotin delivery strategies, protein extraction and enrichment, and mass spectrometry–based analysis. We also highlight emerging quantitative and conditional PL approaches that enable dynamic comparison of proxiomes across developmental stages, environmental conditions, and genetic backgrounds. Throughout, we emphasize the importance of rigorous controls, careful terminology, and orthogonal validation to ensure biologically meaningful interpretation of PL datasets. These guidelines aim to standardize experimental design and interpretation, facilitating reproducible and biologically meaningful PL studies in plant systems.
|
|
Scooped by
mhryu@live.com
September 24, 12:21 PM
|
Protein language models (PLMs) have transformed our ability to learn from evolutionary sequence space, but protein engineering ultimately asks a different question: not what evolution selected, but what we should build next. Zero-shot likelihoods therefore provide useful, but not universal, measures of fitness and can misalign with engineering objectives. Experimental supervision redirects these priors towards properties of interest, enabling target-specific prediction and closed-loop optimization. PLMs thereby complement structure-based design: structural methods provide geometric control, while PLMs integrate experimental feedback to optimize functional and developability properties. Realizing this potential requires evaluation beyond retrospective predictive accuracy, towards extrapolation, multi-objective optimization, and prospective experimental success. We argue for recurring competitions combining scalable predictive benchmarks with prospective experimental challenges. Ultimately, progress should be measured not by predicting existing experiments, but by enabling successful new ones.
|











3 inducible promoter in yeast