 Your new post is loading...

|
Scooped by
mhryu@live.com
Today, 5:01 PM
|
Microbial life strategies are shaped by a fundamental ecological trade-off: specialization enables peak performance in a narrow niche, while generalization allows persistence across diverse environments, but may constrain maximal growth rates. In soils, this trade-off is particularly relevant in the rhizosphere and detritusphere—and at their interface, where co-occurring living roots and decaying residues are hypothesized to generate emergent biogeochemical conditions. Using H₂¹⁸O quantitative stable isotope probing (qSIP), we measured bacterial and fungal growth rates in the rhizosphere, the detritusphere, and in the combined presence of rhizosphere + root detritus. We classified taxa operationally as specialists (defined as microbes actively growing only within a single habitat) or generalists (defined as microbes actively growing in two or more habitats), reflecting realized growth breadth under the conditions tested. Bacterial specialists exhibited faster growth than generalists within the habitats where they grew, a pattern consistent with a trade-off between niche breadth and growth rate. Net relatedness and nearest taxon indices showed that total bacterial communities were phylogenetically clustered, while specialist and generalist communities were phylogenetically random, consistent with functional traits—rather than lineage—predicting realized growth-breadth strategy. In annual grassland soils, fast-growing specialists may dominate ecosystem processes when resources abound, and slow-growing generalists may sustain element transformations when conditions shift; understanding this interplay may inform predictions of soil-carbon trajectories.
|
|
Scooped by
mhryu@live.com
Today, 4:47 PM
|
Coiled coils are a versatile class of α-helical protein motifs characterized by recurring sequence patterns that direct their assembly into defined oligomeric bundles and underpin a wide range of biological functions. The well-established sequence-structure relationships governing coiled-coil formation enable predictive control over stability, specificity, and oligomerization state, making them attractive and chemically tractable building blocks for biosensor design in applications ranging from single-molecule detection to synthetic biochemical circuits and functional nanomaterials. After revisiting the theoretical foundations of coiled-coil architecture, this review outlines strategies to engineer programmable binding interfaces that can be rationally tuned to generate orthogonal, high–affinity interaction pairs, enabling flexible and modular biosensor platforms. Particular emphasis is placed on recent advances in computational and data-driven design approaches, including machine-learning and AI-based strategies, alongside established rational and empirical methods for coiled-coil construction. These complementary design principles underpin the development of coiled-coil-based biosensors and are discussed together with selected application examples to illustrate how engineered coiled-coil interactions support sensitive and specific molecular recognition as well as switchable control in synthetic biology and chemical biology. Overall, this review highlights coiled coils as programmable, stable, and highly designable scaffolds at the interface of molecular engineering, computation, and chemical biology.
|
|
Scooped by
mhryu@live.com
Today, 4:36 PM
|
msDNA, or multi-copy single-stranded DNA, is a small satellite DNA observed in DNA extracts from a bacterial cell. A genetic element, usually found on the chromosome, called a retron, is responsible for producing msDNA. This small single-stranded DNA has a unique structure and is synthesized by reverse transcription from an RNA template. Retrons and msDNA are found in a large variety of different bacterial species. The msDNA molecule has also been developed into an important tool for genetic engineering and genome editing. But the biological function of this unique DNA molecule remained a mystery for decades. Recent discoveries show that a retron element can protect bacteria from infection with a virus (phage) using an abortive infection strategy. And the msDNA molecule is required for this anti-phage property. A historical perspective on this unusual DNA molecule, recent breakthroughs into its functions, and a discussion of the current and possible future directions of study are presented herein.
|
|
Scooped by
mhryu@live.com
Today, 4:22 PM
|
The gut microbiome plays an important role in maintaining human health. Despite the rapid growth of literature and publicly accessible data on the gut microbiome, a large-scale, well-curated database integrating a unified matrix with multiple analytical tools is still lacking. Here, we introduced GutBiomeDB, a comprehensive database and analysis platform for the human gut microbiome. GutBiomeDB contains 168 464 samples from 482 BioProjects, spanning 72 countries, 224 disease conditions, and seven life stages. To improve the reusability and accessibility of data, the uniformly processed taxonomic profiles generated by Abdill et al. were reused without reprocessing to construct a matrix of 4680 taxa and 3142 genera, and disease, life-stage, sex, and geographic metadata were manually curated by our team. Additionally, GutBiomeDB offers four tools for in-depth analysis: “Differential Analysis” for comparing diversity and abundance of user-selected cohorts and performing random-effects meta-analysis across projects; “Interaction Network” for comparing disease and healthy-control co-occurrence networks; “Lifecycle Atlas” for visualizing genus trajectories across seven life stages; and “Health Index” for searching similar samples and scoring uploaded genus profiles. GutBiomeDB serves as a versatile and valuable resource for advancing a broad spectrum of gut microbiome research and clinical relevance. GutBiomeDB is freely accessed at https://gutbiomedb.online.
|
|
Scooped by
mhryu@live.com
Today, 3:58 PM
|
GlyTouCan (https://glytoucan.org) is the international, species-neutral glycan structure repository that assigns stable, globally unique accession numbers to glycan structures independently of the experimental method used to determine them. Here, we describe GlyTouCan version 4, released on June 22, 2026, which introduces a completely redesigned user interface with substantially faster browsing and searching, including a new “archetype” view that groups registrations that differ only in the anomeric or ring form of the reducing-end residue together for clearer filtering of the >256,000 glycans now registered. Version 4 provides an improved graphical structure input, via the updated browser-embedded GlycanBuilder application, for both searching and registering structures. Users may now sign in with an ORCID ID in addition to a Google account, and all previously released v3 REST API endpoints remain fully backward compatible. Version 4 also introduces a framework for industry affiliates, providing a structured pathway for commercial organizations that work with or synthesize glycans, while all existing academic database-partner relationships are maintained. GlyTouCan remains freely available to all users without charge, login, or registration for browsing and searching. We also summarize the repository’s data content, which spans >600 monosaccharide types and, judging from these, includes many glycans of probable bacterial or plant origin.
|
|
Scooped by
mhryu@live.com
Today, 3:50 PM
|
Rod-shaped bacteria grow by inserting peptidoglycan into the lateral cell wall during elongation and into the septal cell wall during division. These two modes of growth are driven by distinct peptidoglycan synthesis machineries that consume the shared precursor Lipid II and must be coordinated so that cell enlargement remains matched to division. However, how cells spatially allocate this shared precursor, and whether Lipid II translocation itself contributes to this coordi-nation, remain unclear. Here we show that the spatial distribution of the essential Lipid II flippase MurJ coordinates this balance in E. coli. Increasing nonseptal MurJ abundance shifted cell-wall synthesis toward elongation and reduced septal synthesis. Single-molecule tracking revealed that MurJ diffuses throughout the membrane but is transiently captured at the division site, rather than stably incorporated into the septal synthesis machinery. This recruitment requires active septal cell-wall synthesis, but not ongoing Lipid II synthesis or flipping, indicating that MurJ recruitment is coupled to the active synthesis machinery rather than to substrate availability or transport. Thus, activation of septal synthesis creates transient MurJ capture at the division site, providing a mechanism to preferentially supply Lipid II for septal growth during cytokinesis. These findings reveal a capture-and-release mechanism that dynamically enriches MurJ at active division sites and thereby coordinates elongation and division in bacterial cells.
|
|
Scooped by
mhryu@live.com
Today, 1:18 PM
|
The metabolism of early microbes shaped our planet's chemistry and enabled more life to evolve. However, it remains uncertain when many forms of metabolism arose and which organisms carried them out. Here we combine machine learning, metabolic networks, and phylogenomics of microbes to date 14 forms of metabolism and 6 other traits. We find that metabolism evolved in three waves, starting >3.4 billion years ago (Ga) with fermentation and sulfur compound respiration. A second wave began ~3.2 Ga with aerobic respiration and growth, while a third began ~1.4 Ga with further specialization. We compared these predictions with independent dates from the geochemical record, and agreement with conservative dates was good (CCC = 0.81 to 0.89). Several forms of metabolism are invisible in the geochemical record, and our approach dates these forms, too. Our results reconcile different lines of evidence for microbial evolution and provide a fuller picture of early Earth.
|
|
Scooped by
mhryu@live.com
Today, 1:07 PM
|
Retrieving an enzyme for a target reaction provides a starting point for evolution, but predicting how to improve it remains difficult. This requires connecting evolutionary information with the structural and chemical context of catalysis. Here we present AlphaEnzyme, an enzyme foundation model built on a structure-grounded representation of an enzyme paired with its reaction, from which catalytic compatibility, kinetics and mutational response are read out together. On a time-separated benchmark, AlphaEnzyme achieves a top-1 catalyst retrieval success rate of 30.1%, against 17.2% for the strongest baseline. Michaelis constant predictions achieve the highest rank correlations among the compared methods, reaching 0.64 for enzymes sharing at most 40% identity with the kinetic training set. The model also enriches high-fitness TrpB variants at a budget of 16 candidates without target-specific fitness training. In prospective transaminase engineering, several prioritized variants exceed the parent, with the best design yielding a 30.4-fold increase in product signal in a lysate-based assay while retaining (R)-selectivity. Together, AlphaEnzyme provides a common molecular basis for selecting starting enzymes and prioritizing sequence changes for their improvement.
|
|
Scooped by
mhryu@live.com
Today, 12:54 PM
|
CRISPR-Cas9 orthologs remain functionally underexplored despite the rapidly growing scale of publicly available metagenomic sequencing data. Here, we applied a multi-stage computational discovery pipeline to two independent sources of metagenomic sequence data, a multi-biome collection of 660,185 metagenome-assembled genomes spanning 17 public catalogs, and raw sequencing reads from human microbiome studies assembled de novo, to identify novel Cas9 orthologs. Candidates were filtered for guide RNA architectural plausibility, sequence novelty, conservation of catalytic residues, and structural integrity, yielding 14 candidates spanning both data sources for experimental characterization. To determine PAM preference at scale, we developed a cost-effective Nanopore long-read-based adaptation of the high-throughput PAM determination assay (NanoPAMDA), enabling rapid, time-resolved, kinetic PAM profiling across many candidates in parallel. One Cas9 effector, E10, showed PAM-specific activity in vitro and was catalytically active in E. coli. Together, these findings demonstrate a scalable, long-read sequencing-based framework for discovering and biochemically characterizing novel Cas9 orthologs from metagenomic data.
|
|
Scooped by
mhryu@live.com
Today, 12:15 PM
|
Quantifying enzyme kinetic parameter changes upon mutations is essential for accelerating enzyme evolution. Current methods focus on predicting absolute values of kinetic parameters (turnover numbers kcat and Michaelis constants Km), yet they fail to accurately capture mutation effects. To our knowledge, no method directly models mutation effects (Δkcat and ΔKm) due to the scarcity of such training data. Moreover, these methods haven’t fully exploited protein structural geometry. Here, we establish a high-quality enzyme mutation effect dataset by pairing wild-type and mutant kinetic parameters measured under identical experimental conditions via a semi-automatic procedure combining language model-assisted parsing and manual verification. Leveraging this dataset, we develop DeltaCata, a Siamese geometric graph neural network to directly predict the changes in kinetic parameters induced by residue substitutions. DeltaCata demonstrates substantial performance improvements over existing methods, especially for enzymes unseen in the training sets. Its utility is further validated through in silico beneficial mutation screening experiments using deep mutational scanning datasets. Finally, we apply DeltaCata to engineer the methyltransferase sGmOMT2, achieving up to a 7.0-fold improvement in catalytic efficiency for in vitro icaritin synthesis. These results suggest the high potential of DeltaCata for industrial enzyme engineering. Predicting how mutations affect enzyme catalytic efficiency remains challenging. Here the authors build a benchmark dataset and develop DeltaCata, a geometric deep learning model that predicts changes in enzyme kinetics and guides enzyme engineering.
|
|
Scooped by
mhryu@live.com
Today, 12:33 AM
|
The intracellular delivery of therapeutic macromolecules remains a major challenge in biomedicine. Capsid-forming proteins are one promising vehicle, but to date, these have required cellular assembly or rely on fusogens for cell entry, limiting their scalability and utility. Here we reconstitute the Drosophila melanogaster Arc1 (dArc1) retroelement-derived capsid entirely from purified recombinant protein components and in vitro transcribed RNA, creating a fully defined, cell-free assembled protein nanoparticle system. We engineered the dArc1 RNA-binding domain to efficiently encapsulate both mRNA payloads and Cas9 ribonucleoproteins. We show that dArc1 capsids bind mammalian cells through a direct interaction with the surface receptor SORCS2. Leveraging this interaction, we demonstrate that intramuscular injection of dArc1 capsids carrying Cas9 gene editors achieves up to 18% exon skipping and restores dystrophin expression in muscle fibers of mdx mice, a model of Duchenne muscular dystrophy. This work demonstrates the potential of in vitro-assembled protein nanoparticles for delivery of molecular cargoes. Capsid-forming proteins are promising vehicles for macromolecule delivery, but have required cellular assembly or fusogens for entry. Here, authors assemble Drosophila Arc1 capsids cell-free, show entry via the receptor SORCS2, and deliver Cas9 editors that restore dystrophin in mdx mice.
|
|
Scooped by
mhryu@live.com
Today, 12:29 AM
|
R-loops are non-canonical nucleic acid structures implicated in diverse cellular processes and diseases. We previously developed R-loopBase to address the pressing challenges of inaccurate R-loop maps and the limited understanding of the R-loop regulatory network. However, R-loopBase provided only human R-loop maps with categorical confidence and did not account for cell type specificity. These limitations, coupled with the emerging R-loop profiling technologies and advances in R-loop regulatory mechanisms, have motivated the development of R-loopBase v2.0 (https://rloopbase.nju.edu.cn). After uniformly re-analysing 358 R-loop mapping datasets generated by 16 technologies, we introduce a quantitative R-loop scoring framework that assesses genome-wide R-loop confidence in human, demonstrating strong concordance with known R-loop biology. We further extend the framework to specific cell types and mouse, fruit fly, and yeast. In parallel, we substantially expand the collection of R-loop regulators across species, enabling the inference of changes in R-loop homeostasis. Building on these expanded datasets, we implement several new interactive features and analytical tools, including an expanded multi-species genome browser, deep learning-based R-loop prediction, R-loop homeostasis analysis, and a streamlined data download portal. We anticipate that R-loopBase v2.0 will serve as an enhanced, up-to-date one-stop resource for the R-loop research community.
|
|
Scooped by
mhryu@live.com
Today, 12:10 AM
|
Statistical literacy is frequently treated in undergraduate and graduate life science training as a technical competency peripheral to experimental practice rather than as a central component of scientific reasoning. This separation is especially problematic in life sciences and related disciplines, where biological variability is intrinsic to living systems and often gives rise to heterogeneous, skewed, multiplicative and non-normal data. Consequently, the interpretation of biological measurements depends not only on the data themselves but also on how variability, distributions, measurement scale, uncertainty and inference are understood. This perspective argues that stronger statistical appreciation is urgently needed in the life sciences, particularly during early scientific training. Emphasis is placed on the biological origins of variability, the interpretation of distributions, the importance of multiplicative thinking and lognormality, the appropriate use of means, medians, geometric means and logarithmic transformations, and the distinction between variability, uncertainty and effect size. The article further discusses replication, outliers, the limitations of significance testing and why statistical thinking should be embedded within bioscience education as an integral part of scientific reasoning rather than taught as an isolated analytical skill.
|
|
|
Scooped by
mhryu@live.com
Today, 4:56 PM
|
An article published by Liu et al. ( 2026, https://doi.org/10.1111/nph.71579) provides compelling evidence that manipulating Ca2+ channel activity can enhance crop resistance to devastating pathogens. The authors studied rice blast, caused by the hemibiotrophic ascomycete fungus Magnaporthe oryzae, which is a devastating disease of rice world-wide. By identifying a hyperactive allele of the rice, CYCLIC NUCLEOTIDE-GATED CHANNEL13 ( OsCNGC13), the authors demonstrate that altered Ca2+ influx can trigger hypersensitive response-like cell death and confer broad-spectrum resistance against rice blast. The hypermorphic allele of rice OsCNGC13, designated elicitor-triggered cell death 1 ( etd1), was identified by a forward genetic screen and exhibits spontaneous cell death and a pronounced hypersensitive response (HR)-like phenotype following exposure to M. oryzae elicitors. etd1 enhances blast resistance by restricting M. oryzae colonization with cell death, and remarkably, it displayed resistance against all 108 tested M. oryzae isolates. Genetic analysis revealed that a single glycine to glutamate substitution (G483E) within the highly conserved CNGC gating region, renders the etd1-encoded version of OsCNGC13 a hyperactive Ca2+-permeable channel. The mutation alters Ca2+ permeability, thereby amplifying the cellular response to pathogen-derived stimuli. This finding demonstrates that a single amino acid substitution in a Ca2+ channel can confer exceptionally broad disease resistance without the need to introduce additional pathogen-recognition specificities.
|
|
Scooped by
mhryu@live.com
Today, 4:40 PM
|
Lager beer, made by fermentation of barley malt using the hybrid yeast Saccharomyces pastorianus, is extremely popular worldwide. The low genetic variation of S. pastorianus strains limits the scope of development for novel lager beer types. The wild ancestor Saccharomyces eubayanus has potential for use in lager brewing, but its application is constrained by formation of phenolic off-flavours (POF+ phenotype) and limited uptake of the wort α-oligoglucosides maltose and maltotriose. Here, we addressed both limitations, using screening and evolutionary engineering of the Himalayan S. eubayanus strain ABFM5L.1, one of the closest known relatives of S. eubayanus subgenome of modern hybrid lager yeasts. Prior to improving α-oligoglucoside utilisation, 4-vinylguaiacol formation was abolished by mutagenesis and screening for POF⁻ mutants. Subsequently, evolution for improved sugar utilisation and reverse engineering identified SeMALR1 (the S. eubayanus ortholog of S. cerevisiae MAL63) as a key regulatory control point. Single-nucleotide substitutions in this maltose regulon activator gene enabled rapid maltose uptake and partial maltotriose utilisation in a previously maltose-negative background. The evolved non-genetically modified POF⁻ strains showed near-complete maltose consumption (>90%–95%) and partial maltotriose consumption (∼25%–32%) in industrial wort. These results reveal substantial regulatory flexibility in Holarctic S. eubayanus and support its further development as a novel lager brewing yeast.
|
|
Scooped by
mhryu@live.com
Today, 4:27 PM
|
Heterologous production of metabolites and proteins requires the transfer of foreign DNA into a host. One common barrier to the genetic engineering of bacteria is their plethora of phage defense systems. Targeted deletion of defense system components can improve DNA transfer for downstream applications. We sought to improve the transformation efficiency of Burkholderia sp. FERM BP-3421, a β-proteobacterial host that has great potential for the high-titer production of bioactive small molecules. We investigated restriction-modification systems and the recently described Kiwa phage defense system. Through deletion of three restriction enzyme genes, transformation efficiency was improved nearly 7-fold. The electroporation protocol was also optimized with respect to temperature, cell density, and buffer composition, which resulted in an additional 40-fold improvement in transformation efficiency, reaching 1 × 10⁶ CFU/µg plasmid DNA. Interestingly, a mimicry by methylation approach, where DNA is pre-methylated using two host DNA methyltransferases, outperformed the transformation efficiency obtained with restriction enzyme deletion mutants nearly 3-fold. Moreover, contrary to previous reports in E. coli, deletion of the Kiwa system did not improve transformation efficiency into Burkholderia sp. FERM BP-3421. Understanding the impact of bacterial innate immune systems on genetic tractability is vital to improving non-model host strains to produce high-value molecules of interest.
|
|
Scooped by
mhryu@live.com
Today, 4:21 PM
|
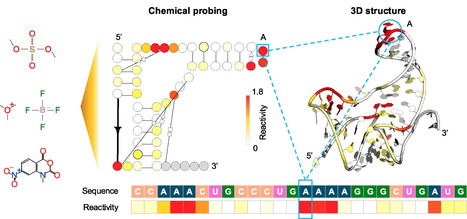
RNA chemical probing generates nucleotide-resolved profiles in vitro and in cells, while X-ray crystallographic or cryo-electron microscopy models provide high-resolution structural models but remain comparatively low throughput. Aligning these experiments from different modalities may provide insights into RNA structure formation and molecular functions. Here, we present Ribocentre-FoldBridge (https://foldbridge.ribocentre.org/), an AI-assisted, curator-reviewed database linking curated chemical-probing profiles with experimentally determined 3D structures. This database catalogues 12 types of RNAs, linking 256 929 probing profiles across five experimental categories to 5321 structure-linked cases. It interactively visualizes the probing profiles that align with RNA secondary and tertiary structures at nucleotide resolution. We demonstrate probe-specific reactivity patterns across paired, unpaired, and solvent-accessible structural contexts. The database aims to provide a reproducible evidence layer for examining RNA structure–function relationships across heterogeneous experiments, and thus facilitate the development of new RNA structure or function prediction programs.
|
|
Scooped by
mhryu@live.com
Today, 3:57 PM
|
The BioImage Archive (https://www.ebi.ac.uk/bioimage-archive) is EMBL-EBI’s flagship resource for life sciences image data. It serves as a deposition database for biological images across scales from near-atomic through to whole organisms, and across imaging modalities. The Archive’s mission is to support the reproducibility of quantitative results based on imaging, support methods development including modern deep-learning-based approaches, and allow large-scale reanalysis of image data. Across the Archive’s ecosystem, we provide access to over 11 PB of image data. Recent developments in underpinning infrastructure now allow interactive exploration, visualization, and streaming access to a subset of the Archive’s data using the new OME-Zarr file format, and will ultimately provide access to all of EMBL-EBI’s archived image data, including data from the Electron Microscopy Public Image Archive. Migration of all holdings and a unified submission system are in progress.
|
|
Scooped by
mhryu@live.com
Today, 2:58 PM
|
Antifungal peptides are promising drug candidates to fight fungal infections in the clinics and agriculture. However, recent data suggest that antifungal peptides might also play a role within their own producing organism to survive nutrient limiting conditions. We have therefore studied the function of the antifungal AnAFP in Aspergillus niger in more detail. To achieve this, we established a Tet-on controlled anafp expression system, which allowed us to study a null and an overexpression phenotype in the same isolate. We observed that increased intracellular AnAFP expression reduces growth of A. niger and prematurely activates autophagy. Comparative transcriptome analyses of glucose-starving mycelium demonstrated that increased anafp expression strongly impacts expression of genes important for cell wall integrity and remodeling, as well as genes with a predicted function in metabolism and transport of carbohydrates, proteins, and lipids. Notably, genes encoding regulators of conidiophore development such as flbC and flbD became induced upon anafp overexpression. Fluorescent analyses of a Tet-on driven AnAFP::eGFP fusion protein congruently unraveled that AnAFP localizes to cell walls and septa of A. niger. Moreover, AnAFP::eGFP expression is spatially restricted to selected compartments only and affected cells displayed a sudden reduction in hyphal diameter. From these data we conclude that AnAFP is important to drive vegetative growth and sporulation in A. niger during nutrient limitation through autophagic recycling. We predict that AnAFP drives nutrient mobilization through selective cell lysis to ensure the survival of the whole colony during phases of starvation.
|
|
Scooped by
mhryu@live.com
Today, 1:11 PM
|
In vivo protein-RNA interactions are mapped almost exclusively by CLIP-seq, which profiles one protein in one cell type per experiment and needs a specific antibody; only about 10% of the roughly 2,000 human RNA-binding proteins have been assayed, and the Protein Data Bank holds around 5,000 protein-RNA complexes, a quarter of them ribosomes. Sequence-based prediction could extend coverage to unprofiled, newly discovered, or designed molecules, but existing predictors are not built for that case. One family trains a separate model per protein and cannot move beyond proteins with CLIP data; the other scores pairs but targets a single RNA class. Most are evaluated with random splits and randomly paired negatives that leave near-identical sequences on both sides of the split, and many require structure or read only short windows, discarding the context around a binding site. Their accuracy falls sharply when whole molecules are held out. We address this with two contributions. First, a strict benchmark of 2.1 million examples built from 11.6 million peaks of CLIP experiments targeting 209 proteins, taken from four public databases, in which each RNA is a spliced transcript with nucleotide-level labels, and sequence-similarity clusters are assigned whole to training, validation, and test sets, giving separate slices for unseen RNAs, unseen proteins, and unseen pairs. Negatives are matched to positives in length and in the number of other proteins binding the transcript, removing the shortcut by which a model predicts binding from how popular a transcript is without reading the protein. Second, RPI-Zero, a sequence-only model that reads any full-length protein and RNA jointly in up to 4,096 tokens, so the RNA representation is conditioned on the protein, and describes every protein as a mixture of shared motif prototypes, placing unseen proteins in the same terms as training ones. One model covers all proteins and RNA classes, uses no structure, and needs no interaction data for a new molecule. Compared with five state-of-the-art methods, it achieves the highest score in eight different metrics on unseen RNAs, unseen proteins, and unseen pairs. The model and data are available at https://github.com/ciceklab/RPI-Zero and https://zenodo.org/records/23748141, respectively.
|
|
Scooped by
mhryu@live.com
Today, 1:05 PM
|
Protein sequence databases are growing far faster than experimentally curated annotations, limiting functional interpretation of newly identified proteins and coding variants. We developed PALM, a protein annotation language model that jointly predicts domain and functional-site occurrence, while preserving overlapping and nested annotations through a soft-target objective. PALM integrates ESM2 with low-rank adaptation (LoRA), learned layer aggregation, and a bidirectional long short-term memory (BiLSTM) encoder. PALM was trained on ~15 million InterPro-annotated UniRef50 sequences spanning 17,951 domain and 1,383 site classes. Across 2.3 million held-out proteins, PALM achieved domain- and site-occurrence F1 scores of 0.941 and 0.877, respectively, and retained substantial performance in proteins with <20% sequence identity to the training and validation data. PALM also substantially outperformed ESM3 annotation baseline. Without training on variant-pathogenicity labels, PALM embedding disruption distinguished 151,823 ClinVar missense variants more accurately than ESM2 embedding disruption (AUROC 0.835 versus 0.710), and combining PALM embedding disruption with the ESM2 likelihood-ratio signal reached an AUROC of 0.877. The same combined zero-shot score outperformed AlphaMissense on a benchmark dataset on 128,161 missense variants, that were derived from literature but not present in ClinVar database. At the protein level, PALM embeddings showed stronger CATH-Gene3D superfamily organization than frozen ESM2 and ESM3 embeddings, and improved prediction of experimental activation and repression effects when combined with ESM2. In a downstream case study, we demonstrated the ability to use PALM-derived embedding as proxy of deep mutational scanning (DMS), showcasing the broad application of PALM. Together, PALM converts curated residue-level knowledge into transferable and mechanistically interpretable representations that connect protein sequence, function, and variant consequence.
|
|
Scooped by
mhryu@live.com
Today, 12:31 PM
|
The global epidemic of metabolic dysfunction-associated steatohepatitis (MASH) is escalating without effective therapies. This study identified a significant depletion of the gut commensal bacterium Faecalibacterium duncaniae (F. duncaniae) as a core feature of MASH. To overcome the poor colonization by traditional probiotics in inflammatory environments, we engineered a living microbial therapeutic by incorporating chiral gold nanozymes onto F. duncaniae. We discovered that biological performance is enantiomer-dependent: the right-handed nanozyme (D-Au) serves as a superior ROS-scavenging shield, protecting the probiotic from oxidative assault and enhancing its colonization in the inflamed gut. In mouse models of MASH, this engineered probiotic (F@D-Au) reversed disease progression, ameliorating steatosis, inflammation, and fibrosis. It further restored systemic homeostasis, rectifying dysbiosis, metabolic disturbances, and—notably—MASH-associated cognitive impairment. Metabolomic analyses revealed that this multi-organ benefit was linked to the restoration of key microbial metabolites, including kynurenic acid and linoleic acid. Our work establishes a new class of chirality-enhanced living therapeutics that precisely remodel the gut–liver axis, offering a transformative strategy for treating MASH and its complications.
|
|
Scooped by
mhryu@live.com
Today, 12:49 AM
|
Volatile organic compounds (VOC) are interpreted as transient, unidirectional signals in plant–microbe interactions. We argue that this reductionist framing obscures their emergent role as regulators of ecological network dynamics, influencing stability-associated properties of plant–microbe systems. We propose a conceptual framework based on five principles (gradient logic, blend emergence, feedback reciprocity, threshold switching, and multiscale coupling) and use it to generate falsifiable predictions for how plant-derived and microbial VOCs operate as a cross-kingdom regulatory network shaping microbiome assembly, plant physiological plasticity, and multitrophic interactions. Key mechanistic gaps are critically evaluated alongside testable approaches for probing volatile-mediated ecological dynamics. Viewing volatile networks as adaptive ecological infrastructure reframes plant–microbiome resilience with implications for sustainable agriculture and ecological restoration under global change.
|
|
Scooped by
mhryu@live.com
Today, 12:31 AM
|
GlycoPOST (https://glycopost.glycosmos.org) is a public mass spectrometry (MS) data repository for submitting and sharing glycan-related raw MS data along with structured experimental metadata, in accordance with the Minimum Information Required for A Glycomics Experiment (MIRAGE) guidelines. As of 1 September 2026, GlycoPOST hosts 602 projects containing 7.6 TiB of data, of which 445 are publicly available. In this update, we implemented major updates to GlycoPOST, expanding its scope from glycomics to glycoproteomics by incorporating the recent revisions published on the MIRAGE MS guidelines, in addition to enabling users to filter “presets,” which are units for metadata in GlycoPOST, by keywords and last update date. The newly introduced concept of “project type” enables each GlycoPOST submission, referred to as a “project,” to be classified according to whether it contains glycomics or glycoproteomics data. This makes it easier to select reusable metadata profiles (presets) by displaying only categories relevant to the experimental field. Furthermore, with the introduction of a project type specifically designed for glycomics-assisted glycoproteomics experiments, it is now possible to register data and metadata from both glycomics and glycoproteomics within a single project. These updates will promote standardized data sharing and reanalysis across glycomics and glycoproteomics using GlycoPOST. glycosylation
|
|
Scooped by
mhryu@live.com
Today, 12:15 AM
|
Obtaining sufficient quantities of purified proteins in their intended molecular states is essential for biological research and protein engineering. Advances in computational protein design have expanded the functional capabilities of de novo proteins and accelerated candidate generation. However, reliable methods for ranking expected monomeric yield of candidate de novo designs, including molecular binders, fluorescent proteins and enzymes, have yet to be established. Standardized measurements of monomeric yield across diverse sequences remain scarce, limiting our understanding of its determinants and the development of accurate predictors for candidate selection. Here we developed a scalable pooled assay combining peptide barcodes, size-exclusion chromatography and mass spectrometry to quantify monomeric yield for over 39,000 natural protein domain variants, de novo proteins and nanobodies under uniform and standardized E. coli production conditions. We used this dataset to (1) quantify the relationship between folding stability and monomeric yield, (2) benchmark inverse-folding methods, (3) evaluate the utility of structure-prediction confidence metrics in selecting high-yield design candidates, and (4) identify sequence and structural patterns in nanobodies associated with monomeric yield and monomer-to-dimer yield ratios. We further developed ESMC-MonoYield, a protein language model fine-tuned to predict monomeric yield from amino acid sequence alone, and prospectively demonstrated enrichment of high-yield candidates among BindCraft-designed binders. Our approach enables standardized, large-scale measurement of monomeric yield across diverse proteins, and establishes monomeric yield as a sequence-encoded property that can be learned, predicted and ultimately designed.
|











directed evolution, hts,
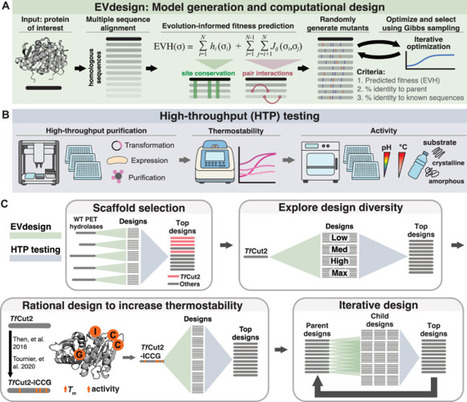
EVdesign starts by collecting homologs of the parent enzyme into an alignment and fitting a statistical model (EVcouplings) of per-position conservation and pairwise covariation, whose summed score (the evolutionary hamiltonian) serves as predicted fitness. Candidate sequences are then generated by Gibbs sampling: from a random start, each position is resampled over all 20 amino acids in proportion to an objective that weighs predicted fitness (0.34) against sequence distance to the parent and to other designs (0.66), while enforcing a mutation range such as 10 to 15% of positions, with the inverse temperature raised from 0.5 to 10 so sampling converges. About 1000 designs are generated, clustered hierarchically to pick a diverse set, and synthesized for testing of expression, thermostability by DSF, and activity across substrates, pH and temperature. The best designs become new parents for further rounds, with already mutated positions fixed and 7 to 9 new substitutions each, and rational mutations (the four ICCG substitutions) were added between rounds to fix thermostability.