Your new post is loading...

|
Scooped by
mhryu@live.com
Today, 1:02 AM
|
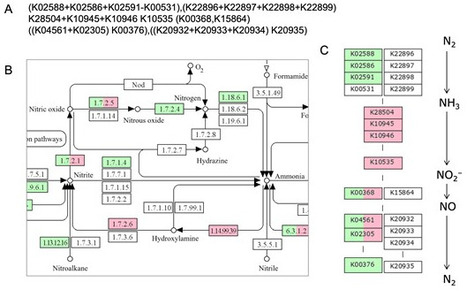
The KEGG database (https://www.kegg.jp) has been developed as a model of the biological systems. By organizing knowledge of cellular and organism-level functions in the form of molecular wiring diagrams, the model enables generating new knowledge and finding practical applications. The KO (KEGG Orthology) dataset plays the basic role of organizing knowledge. KO is an ortholog with functional relevance, generalizing experimental evidence in specific organisms to other organisms. KEGG molecular networks, including pathway maps and modules, are generic networks with KOs as network nodes, and thus KEGG mapping from genomes to pathways can be applied to any organism. As the number of KOs increases and the KO annotation rate improves, KEGG mapping is further expanded. A set of KOs in the genome and a set of modules in the metabolic pathways are now used to characterize various data objects in the biosphere, including organisms, organism groups, microbiomes, viruses, and their combinations, such as endosymbiont–host, microbiome–host, and virus–host relationships. Furthermore, a simple measure of similarity either by KO compositions or module compositions is introduced to compare organism groups. The resulting similarity dendrograms possibly reflect similarity of cellular functions or, more specifically, metabolic functions, which can be compared with phylogenetic trees.
|
|
Scooped by
mhryu@live.com
Today, 12:40 AM
|
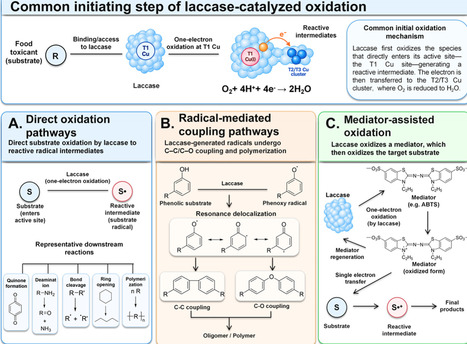
As a copper-containing polyphenol oxidase, laccase (EC 1.10.3.2), first isolated from the Japanese lacquer tree (Rhus vernicifera), is widely present in fungi, plants, and bacteria. It has shown considerable potential in food detoxification owing to its mild reaction conditions, broad substrate range, and environmental compatibility. This allows laccase to oxidize structurally diverse substrates, although catalytic efficiency varies with substrate structure, redox potential, and accessibility to the active site. Laccase can promote the degradation, transformation, removal, or detoxification of food toxic substances, including biogenic amines, polycyclic aromatic hydrocarbons, phenolic compounds, mycotoxins, and pesticide residues, through substrate oxidation initiated by electron transfer at copper-containing active sites. This review summarizes the mechanisms underlying laccase-mediated degradation, transformation, removal, and detoxification of food toxicants, together with optimization strategies including protein engineering, mediator regulation, and immobilization, supporting its development as a versatile biocatalyst for food safety control.
|
|
Scooped by
mhryu@live.com
October 26, 11:44 PM
|
Genomic duplication is a common type of structural variation that has important roles in gene dosage regulation and contributes to the development of various human diseases including cancer and inherited disorders. However, current genome-editing technologies are limited in their ability to introduce precise and efficient DNA duplications. Amplification editing (AE) is a genome-editing strategy that enables efficient and precise duplication of genomic sequences ranging from tens of base pairs to chromosomal scales. AE offers high precision and efficiency and the ability to duplicate endogenous sequences across multiple targeting sites and in diverse cell types. Here, we describe detailed procedures for the design, execution and analysis of AE-based genomic duplication. These include protocols for duplicating endogenous loci across a range of fragment sizes, as well as workflows to quantify editing efficiency and validate duplication outcomes. In addition, we provide guidance for optimizing AE performance and extending its applicability across diverse genomic targets and experimental contexts. Most AE experiments can be completed within 2 weeks, supporting efficient implementation of targeted genomic duplication in mammalian cells. Here, the authors provide a protocol for amplification editing, a genome-editing strategy using prime editors that enables efficient and precise duplication of genomic sequences ranging from tens of base pairs to chromosomal scales in diverse cell types.
|
|
Scooped by
mhryu@live.com
October 26, 11:10 PM
|
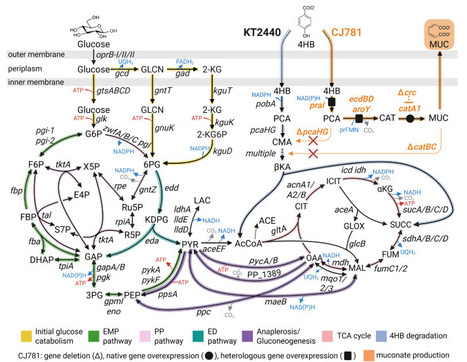
Muconic acid is a versatile platform chemical that can be biologically produced from lignocellulosic substrates, including from lignin-related aromatic compounds. Pseudomonas putida has been previously engineered to convert lignin-related aromatic compounds to muconate at quantitative molar yields. This high atom efficiency requires a supplemental carbon and energy source to support bacterial growth, and central carbon metabolic efficiency and its interaction with aromatic catabolism are underexplored. Here, we applied proteomics, metabolomics, and 13C-fluxomics to quantitatively compare central carbon and energy metabolism in wild-type P. putida KT2440 and a muconate-producing strain, P. putida CJ781. During cultivation on glucose and 4-hydroxybenzoate, CJ781 showed increased glucose uptake, reconfigured central fluxes, and increased extracellular leakage of aliphatic acids relative to wild type. These altered fluxes supported a 3-fold higher intracellular ATP concentration and a model-predicted 2.5-fold increase in apparent ATP excess over anabolic demand. Pyruvate and acetate secretion in CJ781 was mitigated by debottlenecking TCA-cycle entry via citrate synthase overexpression. Furthermore, tuned expression of the catechol dioxygenase and protocatechuate decarboxylase enabled the production of 36.3 g L-1 muconate at 1.1 g L-1 h-1. Overall, this work reveals how P. putida redirects carbon and energy fluxes to support aromatic bioconversion for improved bioproduction from renewable feedstocks.
|
|
Scooped by
mhryu@live.com
October 26, 5:46 PM
|
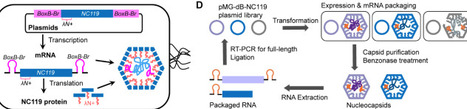
Molecular self-assembly provides a route to nanoscale structures with defined sizes and shapes. Protein cages assembled from repeated subunits form compartments that can package molecular cargoes. Although amino acid substitutions can alter intersubunit interactions and cage architecture, how protein backbone connectivity relates to the cage architectures accessible during laboratory evolution remains unclear. Here we evolved an artificial nucleocapsid from a circularly permuted variant of Aquifex aeolicus lumazine synthase (AaLS). Laboratory evolution increased the yield of purified nucleocapsids relative to the progenitor, and the evolved variant, NC119-3, packaged its encoding mRNA. Cryo-electron microscopy revealed a heterogeneous population of cages, within which we resolved 180- and 210-subunit cage families composed of 36 and 42 pentamers, respectively. Within each resolved family, particles with the same subunit stoichiometry differed in the arrangement and orientation of their pentameric building blocks. A 2.90 Å reconstruction of a tetrahedral 180-subunit cage further revealed that sequence-identical subunits adopt distinct conformations depending on their positions within the assembly. These pentamer-based architectures differ from the domain-swapped T = 4 cage previously reported for nucleocapsids evolved from an AaLS variant with a different circular permutation site. Together with previous work, these findings show that RNA-packaging nucleocapsids evolved from scaffolds with different backbone connectivity can adopt distinct cage architectures.
|
|
Scooped by
mhryu@live.com
October 26, 5:27 PM
|
RNA viruses encode multiple layers of information within a single molecule, which functions simultaneously as a template for protein synthesis and as a structured regulatory RNA. These structures control key aspects of viral gene expression, govern host interactions, and mediate immune evasion. Although the prevalence of RNA structure in viral genomes is now well established, only recently have functional and mechanistic studies begun to uncover how these elements act as regulatory modules that shape infection outcomes. With their compact genomes and experimentally tractable life cycles, RNA viruses represent powerful model systems for uncovering the fundamental building blocks of riboregulation and illuminating principles of gene control conserved across eukaryotes. Here, we review current mechanistic understanding of RNA structure-based regulation across diverse viral families and draw parallels to structure-mediated gene control in eukaryotic transcriptomes, highlighting RNA structure as a central regulatory layer in gene expression with broad therapeutic and synthetic biology potential.
|
|
Scooped by
mhryu@live.com
October 26, 3:01 PM
|
Droplet microfluidics underpins many single-cell, precision biomedical, and nanomaterial techniques. However, implementing these methods reproducibly remains challenging outside specialized laboratories due to high equipment costs, operational inflexibility, mechanical impracticality at the microscope stage, as well as open-source pumping solutions that are inadequately validated for low-flow stability. We present an accessible, research-grade, open-source droplet microfluidics platform integrating a compact, microfluidics-optimized microscopy stage with networked syringe-pump control. Designed for local digital fabrication, primarily 3D printing, and widely available components, the platform supports reproducible builds across diverse settings. This setup enables stable droplet generation, observation of rapid droplet dynamics, and automation-ready networked workflows. The microscopy module uses a Raspberry Pi camera and microsecond stroboscopic illumination to capture sharp images of fast-moving droplets without the need for a high-speed camera. A modular hardware interface and extensible, web-accessible software stack provide a path to integrate additional modules and laboratory automation beyond the configuration evaluated here. For infusion, we introduce an open-source syringe pump optimised for low reliable flow rather than maximum rates, combining gearbox-assisted stepper mechanics with workflow-centric control that enables manual intervention (keypad control) and remote operation (web interface and automation hooks). We benchmark droplet regimes, size tuning, and time-stability under low-flow conditions (between 25 and 2500 uL/h) relevant to advanced assays and demonstrate biomedical readiness through the encapsulation and incubation of cells, beads, and bacteria in monodisperse droplets. The platform has been replicated across laboratories in Latin America and globally, including independent builds, supporting reproducibility. All design files, firmware/software, analysis notebooks, and benchmark datasets are openly released.
|
|
Scooped by
mhryu@live.com
October 26, 2:13 PM
|
Calcium phosphate biomineralization plays a crucial role in the formation of geological deposits, biological materials, and environmental remediation. While microorganisms are known to influence calcium phosphate precipitation, the relative contributions of bacterial cell surfaces and extracellular polymeric substances (EPS) remain poorly defined. This study presents the first microscale investigation of the distinct roles of Gram-positive and Gram-negative bacterial cells and EPS in regulating hydroxyapatite (HAp) mineralization, employing abiotic, EPS-mediated, and bacterial precipitation systems. Zeta potential measurements and Fourier Transform Infrared Spectroscopy (FTIR) revealed that both bacterial cells and isolated EPS provide negatively charged, chemically distinct interfaces capable of interacting with dissolved Ca2+ ions. Solution chemistry demonstrated greater phosphate and calcium ion depletion in biotic systems, consistent with enhanced crystal precipitation compared to abiotic controls. Field emission scanning electron microscopy (FESEM) and Brunauer–Emmett–Teller (BET) analyses showed that biological interfaces produced distinct crystal morphologies and surface characteristics. X-ray diffraction (XRD) revealed significant differences in phase composition: abiotic precipitation produced mixed calcium phosphate phases, whereas EPS-mediated precipitation promoted nucleation but remained dominated by precursor phases. In contrast, whole-cell systems favored HAp formation, with Sporosarcina pasteurii producing phase-pure crystalline HAp and Pseudomonas fluorescens producing HAp-dominant precipitates. Acid dissolution experiments further confirmed the increased stability of biogenic precipitates. These findings demonstrate that the spatial organization of bacterial surface functional groups, rather than surface charge alone, governs hydroxyapatite phase evolution, crystal growth, and mineral stability. While localized metabolic activity may contribute to microenvironmental conditions, the results highlight the importance of bacterial cell surfaces and EPS as key determinants of hydroxyapatite biomineralization, providing a mechanistic basis for the design of biologically mediated mineral materials.
|
|
Scooped by
mhryu@live.com
October 26, 10:53 AM
|
Recent advances in biological foundation models have enabled new opportunities for data-driven molecular engineering. However, designing programmable RNA devices remains challenging because of the vast, nonlinear sequence-structure-function landscape. Here, we present Ernie-Switcher, a deep learning framework built upon the RNA foundation model (RNAErnie), comprising three coupled components: (i) integration of RNAErnie-derived sequence-phenotype representations for realistic design generation and filtering; (ii) characterization of RNA landscape navigability as a theoretical basis for sequence optimization; and (iii) incorporation of biophysical constraints to maintain optimization trajectories within biologically plausible bounds. We validated Ernie-Switcher using RNA toehold switches. Theoretically, the observed lower bound on threshold navigability (86.4%) of the RNA landscape supports the theoretical feasibility of RNA switch sequence optimization. Experimentally, the optimized toehold switches achieved ON/OFF expression ratios of up to 35-fold in E. coli. Collectively, RNAErnie-guided sequence optimization provides a scalable strategy for engineering high-performance RNA devices. To facilitate broad adoption, we deployed Ernie-Switcher as a freely accessible web platform.
|
|
Scooped by
mhryu@live.com
October 26, 10:24 AM
|
A focus on the gene alone has become outdated. Books that capture the complexity of life deserve centre stage.
|
|
Scooped by
mhryu@live.com
October 25, 4:52 PM
|
Extracellular electron transfer (EET) at the cell–electrode interface is central to microbial electrochemical technologies. It remains constrained by the low conductivity of individual cells, physiological impairment associated with coating the cell surface with an interconnected, conductive polymer layer, and a limited capability for biofilm formation. Here, we develop a conductive, enhanced, and dynamic biohybrid system to overcome these barriers. We establish a recovery strategy for Shewanella oneidensis MR-1 cells coated with a conductive polydopamine (PDA) nanoshell, restoring cellular physiology while retaining the coating. The recovered cells exhibit enhanced EET and reduced charge-transfer resistance. We further promote biofilm formation in the recovered PDA-coated cells using a cyclic dimeric guanosine monophosphate (c-di-GMP)-targeted optogenetic approach. This integrated strategy generates a highly conductive, enhanced electrode biofilm with further improved EET and reduced charge-transfer resistance. This work highlights the importance of preserving cell physiology in the design of conductive biofilms and establishes a framework that integrates material coating with biofilm engineering for advanced bioelectronic interfaces.
|
|
Scooped by
mhryu@live.com
October 25, 4:39 PM
|
Many plant species can efficiently adjust their metabolism to a changing temperature regime. As growth temperature significantly influences plant development, growth and distribution, it is of utmost importance to reveal how metabolism is linked to genetic regulation and phenotypic output. Key regulatory mechanisms include transcription factors which mediate responses to low and elevated temperatures, integrating signals related to carbon and nitrogen balance. Advances in high-throughput experimental techniques, mathematical modeling, and machine learning have deepened our understanding of gene regulatory networks, metabolic compartmentation, and the feedback loops between metabolism and gene expression. However, the complex, highly compartmentalized structure of plant cells poses challenges for interpreting metabolic regulation, particularly regarding subcellular allocation of sugars and energy signaling pathways. This review aims at identifying limitations of both experimental and computational analysis of plant metabolism which currently prevent the generation of predictive models of plant physiology in a changing temperature regime. Advances of machine learning and multi-omics integration are discussed in context of how genome sequence information can be linked to metabolic and phenotypic outcomes.
|
|
Scooped by
mhryu@live.com
October 25, 12:53 PM
|
Intervening proteins, or inteins, are mobile genetic elements characterized by their ability to rearrange peptide bonds through a post-translational, self-splicing reaction. Here, we expand the scope of a prior investigation to reexamine the distribution of inteins across archaea and bacteria. This update represents 20- and 50-fold increases in archaeal and bacterial genomes, respectively. In accordance with previous findings, inteins are enriched in DNA replication, recombination, and repair (RRR) proteins, but they are substantially more prevalent in archaea than bacteria, a difference twice that previously reported. Moreover, mini-inteins lacking homing endonucleases (HENs) are more common in bacterial inteins, suggesting bacterial inteins undergo HEN domain loss more frequently than archaeal inteins. This reduction in the prevalence of HENs, the drivers of intein mobility, offers a potential explanation for the lower density of inteins in bacteria than in archaea. Furthermore, certain classes of bacterial intein-containing proteins primarily contain mini-inteins rather than full-length inteins. The enrichment of mini-inteins within certain bacterial protein classes suggests that HEN domains may impose a greater functional cost in these proteins, creating selective pressure for HEN domain loss and resulting in reduced intein mobility.
|
|
|
Scooped by
mhryu@live.com
Today, 12:55 AM
|
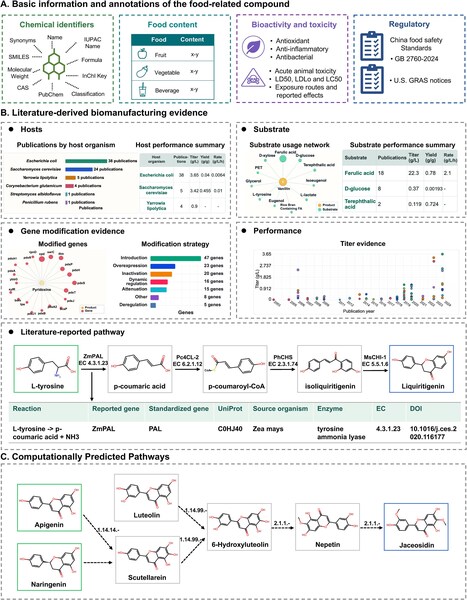
Enabled by synthetic biology and metabolic engineering, microbial biomanufacturing is reshaping the production of food-related compounds by offering sustainable alternatives to resource-intensive extraction and conventional chemical synthesis. However, information linking food-related compounds to biosynthetic pathways and microbial biomanufacturing evidence remains fragmented across the literature and poorly represented in existing food-oriented resources, hindering cross-study comparison, evidence synthesis, and rational design of microbial production systems. Here, we present SynBioFooDB (https://synbiofoodb.biodesign.ac.cn/), a knowledgebase dedicated to synthetic biology-driven food biomanufacturing. SynBioFooDB integrates 74 237 food-related compounds with standardized chemical identities and annotations covering food occurrence, bioactivity, toxicity, and regulatory information. It further provides expert-curated biomanufacturing evidence for 1054 compounds from 5592 publications, linking microbial hosts, substrates, genetic modifications, and quantitative production metrics through structured and traceable records. The database also contains 2002 literature-reported biosynthetic pathways for 971 compounds, enabling comparison of alternative precursors, enzyme combinations, and pathway architectures. For compounds without literature-reported pathways, SynBioFooDB provides computationally predicted candidate pathways to facilitate pathway prioritization and experimental evaluation. By integrating compound-level context, biomanufacturing evidence, and biosynthetic pathway information, SynBioFooDB supports systematic exploration, comparison, and rational design of microbial production strategies for food-related compounds.
|
|
Scooped by
mhryu@live.com
Today, 12:06 AM
|
Metagenomic sequencing has transformed our view of the global viral diversity, yet a fundamental bias limits our understanding of the diversity of complete viral genomes. Current quality assessment tools rely on identifying circular contigs, systematically underestimating the completeness of linear DNA and RNA viruses, thus leaving a large fraction of the virosphere uncharacterized. Here, we overcome this bias, by leveraging within-species genomic termini conservation across diverse metagenomic datasets. Applying this approach to the metaVR database, we recover and validate 1,585 conserved, complete linear viral genomes, representing a 21-fold increase in recognized linear completeness. Our results reveal previously uncovered complete monopartite RNA genomes and individual segments of multipartite viruses across 13 classes, alongside deeply branching viral dark matter. Furthermore, we expand the known physical boundaries of linear DNA viruses, by recovering intact megaphages up to 220 kb and distinguishing true complete genomes from highly transcribed operons. Ecological profiling reveals a strong enrichment of these reassigned as complete linear viruses in specific ecosystems, highlighting their ecological relevance. By enabling systematic recovery of complete linear genomes, this framework unlocks a previously hidden fraction of the virosphere and reshapes our understanding of viral diversity and evolution. Metagenomic tools underestimate linear viral genome completeness due to circularity bias. In this study, the authors track within-species genomic termini conservation across metagenomic datasets to recover and validate 1,585 complete linear viral genomes, revealing a 21-fold expansion of hidden RNA and DNA viruses.
|
|
Scooped by
mhryu@live.com
October 26, 11:36 PM
|
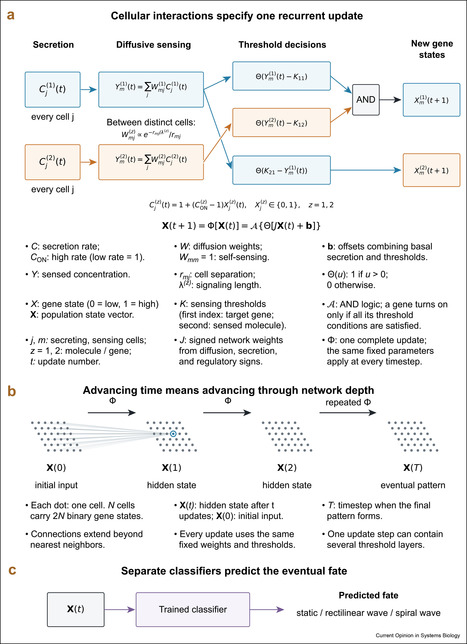
Biological systems have long supplied ideas about computation. Abstracting self-reproduction helped establish cellular automata, while abstracting neural interactions yielded models of associative memory and learning. Biological self-organization offers another, timely opportunity: to investigate how collective dynamics contribute to computation and what limits our ability to predict its outcome. Here we review models of communicating cells, tracing their development from cellular autonomy and effective energy landscapes to persistent spatial dynamics and dynamically constructed predictability. A generalized cellular automaton of secrete-and-sense cells admits an exact representation as a recurrent threshold network, with long-range cellular interactions specifying its connections. This mapping lets us follow self-organization as computation through successive hidden states. In this deterministic model, tested machine-learning predictors initially failed to forecast an already-determined fate but succeeded as self-organization constructed structures that enabled prediction. Recent neural-network studies identified collective modes that supported signal propagation, suggesting further connections between self-organization and machine-learning inference. Together, these findings show how abstracting biological rules gives us a way to investigate fundamental questions about computation: how interactions generate computational capabilities, how collective structures make outcomes predictable, and how much computational effort prediction requires.
|
|
Scooped by
mhryu@live.com
October 26, 6:06 PM
|
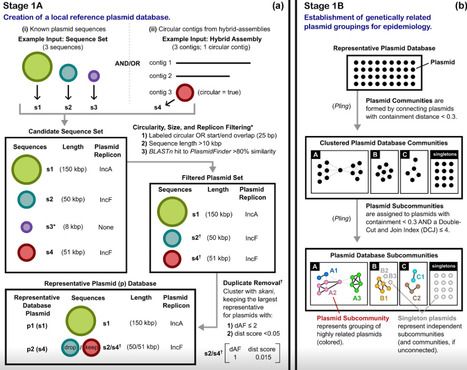
Plasmids are extrachromosomal mobile genetic elements that often carry genes responsible for antimicrobial resistance. Plasmid epidemiology aims to track the evolution and spread of plasmids, but the field currently faces significant barriers that make practical implementation using whole-genome sequence data difficult. Hybrid-assembled genomes remain the most reliable way to identify and track complete plasmids; however, most genomic surveillance data exist in the form of short-read sequencing, which lacks the resolution required to accurately resolve plasmids. Despite recent advances, long-read-only assemblies have not yet reached the consistency seen in hybrid assemblies. The ideal approach to plasmid epidemiology using whole-genome sequence data would consider the limitations of sequencing technologies and the constraints of existing genomic surveillance infrastructure, in addition to the unique evolutionary biology of plasmids. Here, we present Assembly-based Circular Contig Identification for Outbreaks (ACCIO), a tool which creates a reference plasmid database and uses it to infer which plasmids, and genetically related plasmid groupings, are present in an input assembly (Illumina, Nanopore or hybrid assembly). We validated ACCIO using an internal dataset of 303 plasmid-harboring bacterial clinical and surveillance isolates collected from a single acute tertiary care centre. When highly related database plasmids were grouped together, ACCIO achieved 100% sensitivity and 92.1% positive predictive value (PPV) for detection of plasmid groups using hybrid assemblies, and comparably strong performance for Illumina (93.0% sensitivity, 86.6% PPV) and Nanopore (79.3% sensitivity, 91.4% PPV) assemblies. Evaluation on three external datasets yielded consistently high performance. Finally, when benchmarked against MOB-suite, a tool for reconstruction and typing of plasmids, ACCIO demonstrated superior performance across nearly all assembly types and plasmid grouping levels. By integrating database construction, clustering, and plasmid calling into a single workflow compatible with all major sequencing platforms, ACCIO is intended to help advance plasmid epidemiology beyond its current technological and infrastructural barriers.
|
|
Scooped by
mhryu@live.com
October 26, 5:39 PM
|
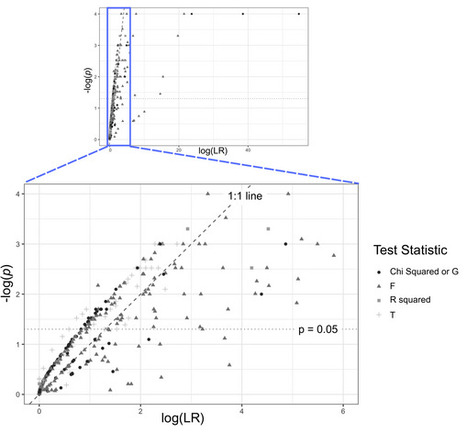
The use of p-values and statistical significance testing as the primary mode of inference in science has been long debated among statisticians and more recently among ecologists. Ecological literature has discussed embracing other modes of inference, such as Bayesian statistics and the use of direct likelihood inference. We reviewed ecology, evolution, and environmental science literature covering the past three decades to investigate trends in the use of different modes of inference over time and to assess the degree of discrepancy between reported p-values and calculated likelihood ratios. p-Values and likelihood ratios were found to scale in a more direct way for single degree of freedom tests, but in a more complex manner for models with more than one parameter. These results demonstrate the degree to which the likelihood ratio (a measure of evidence) differs from a p-value, a measure of uncertainty that is widely presented as a measure of evidence among publications within the fields of ecology and evolution. Additionally, our investigation revealed that modes of inference within ecological studies changed little over the 20-year time period, indicating a failure to adopt alternative modes of inference. We also found downward trends in the reporting of p-value thresholds (e.g., “p < 0.05”) in two journals, with no change in three others. The prevalence of the divergence in the measure of evidence and the p-value measure of uncertainty remains to be confirmed in other journals, time points, and subfields. An overreliance on p-values alone can alter the conclusions drawn from research, impacting management of species and ecosystems. We recommend that authors report both a measure of evidence and uncertainty, and justify their mode of inference in an attempt to produce statistical results that are comprehensive, replicable, and reliably interpretable.
|
|
Scooped by
mhryu@live.com
October 26, 5:13 PM
|
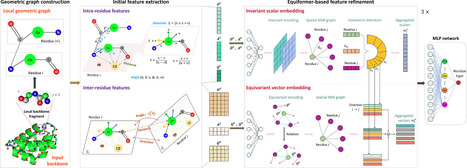
Designing amino acid sequences that uniquely fold into target three-dimensional conformations defines the protein inverse folding problem, a formidable bottleneck in de novo protein design. Current computational paradigms, including deep learning-based approaches, often struggle to reconcile high sequence accuracy with structural stability, computational efficiency, and generalizability across diverse protein families. Here, we present EquiDesign, a deep learning framework that surmounts these constraints via a novel multistep Equiformer-enhanced architecture. By disentangling geometric features into invariant scalars and equivariant vectors, EquiDesign preserves the intrinsic directional topology of the protein backbone during message passing. This is achieved through spatial K-nearest neighbor graph construction and geometric attention mechanisms that hierarchically fuse multiscale contextual information, yielding a physically grounded representation of protein conformations. Extensive benchmarking demonstrates that EquiDesign achieves superior sequence recovery on standard and challenging test sets compared with state-of-the-art methods. Critically, the generated sequences exhibit exceptional structural fidelity, folding stability, and sequence diversity, as validated by comprehensive controls against training-set memorization, compositional bias, and physical energy landscapes, alongside targeted diversity sampling. These results establish EquiDesign as a robust, scalable, and generalizable inverse folding solution, driven by SE(3)-equivariant encoding and multiscale geometric attention, thus propelling de novo protein design toward unprecedented structural precision.
|
|
Scooped by
mhryu@live.com
October 26, 2:38 PM
|
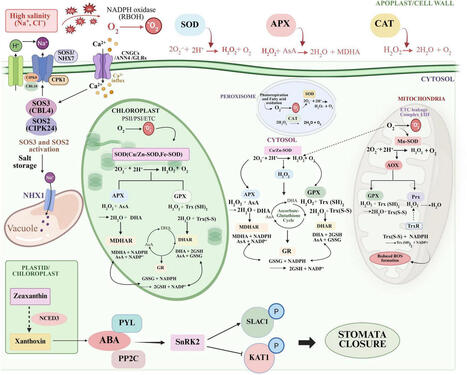
Salinity stress represents a significant environmental challenge that affects plant growth, resulting in adverse impacts on crop productivity and overall yield. Salt accumulation in plants affects cellular homeostasis and provokes osmotic and ionic imbalance. It stimulates higher reactive oxygen species (ROS) production leading to oxidative stress damage and eventual cellular dysfunction. Beneficial microorganisms like plant growth-promoting rhizobacteria, arbuscular mycorrhizal fungi, endophytic fungi, and rhizosphere-associated microbes have recently emerged as resources for sustainable solutions to enhance plant resiliency against salinity stress. Their effects can involve osmotic adjustment, ion sequestration, oxidative-stress mitigation, phytohormone regulation, and rhizosphere-mediated stress buffering. The mechanisms to impart such benefits may include improved nutrients acquisition, assist in osmotic regulation, modulation of phytohormones signaling, and maintenance of cellular ion homeostasis. Often, beneficial microorganisms carry the potential to trigger both enzymatic and non-enzymatic antioxidant defense mechanisms. These responses contribute to oxidative-stress mitigation, yet, their interpretation requires contemplation of fine balance between oxidative damage and plant responses. For example, selected microbial inoculation studies have reported changes in the activity of crucial antioxidant enzymes, like superoxide dismutase, ascorbate peroxidase, catalase, and glutathione reductase. However, the magnitude and the direction of these responses are context dependent. Multi-omics approaches, including amplicon and shotgun metagenomics, metatranscriptomics, host transcriptomics, proteomics, and metabolomics, have expanded our understanding of the taxa, genes, transcripts, proteins, and metabolites associated with plant–microbe interactions under salinity. Therefore, here an effort has been made to present the evidential support for reported microbial effects and their proposed mechanisms of salt tolerance, with a focus on enzymatic and non-enzymatic defense mechanisms and the learnings of multi-omics studies. Frontier integrative mechanisms, including microbiome engineering, synthetic microbial consortia, and systems biology frameworks, are discussed for cultivating climate-resilient crops and sustainable agricultural systems in the salt-affected environments.
|
|
Scooped by
mhryu@live.com
October 26, 1:59 PM
|
Improving the fidelity of computational eukaryotic models will require an enormous amount of high quality and reproducible data from biological experiments. In this study we present and demonstrate a modular 12-channel micro-chemostat system. This micro-chemostat is designed for use by Genesis, a Robot Scientist developed to automate scientific research in yeast systems biology. We performed bioreactor characterization experiments to evaluate the performance of the micro-chemostat system. We also cultivated the Saccharomyces cerevisiae reference strain, BY4741, at three different dilution rates (0.1, 0.2, and 0.3 h−1) and under two aeration conditions (microaerobic and aerobic), resulting in six different conditions. The bioreactor performance fulfilled our requirements, and enabled substrate-limited continuous cultivation of yeast. Furthermore, the empirical results from the biological experiments were consistent with the literature, suggesting that results obtained from our system are comparable to those reported for other platforms in the field. Based on the evidence presented in this study, we conclude that the 12-channel micro-chemostat system is a suitable platform for yeast systems biology research. The modular design of the micro-chemostat system enables future scaling to hundreds or thousands of concurrent chemostats and facilitates integration with autonomous agents for automated optimization and improvement of eukaryotic model systems.
|
|
Scooped by
mhryu@live.com
October 26, 10:34 AM
|
α-1,3-Glucan is a major component of the Aspergillus cell wall. However, unlike β-1,3-glucan and galactomannan, α-1,3-glucan was not previously considered to be released in a soluble form. Therefore, its potential as a diagnostic biomarker has remained largely unexplored. In this study, we engineered α-1,3-glucanase mutants to develop α-1,3-glucan-specific binding proteins and detection systems. Mutants derived from the endo-type α-1,3-glucanases, AGN1 and AglKA, were generated, among which AglKA-CatD-D1090A lacked enzymatic activity but retained strong binding affinity for α-1,3-glucan. Using this probe, we established a split luciferase assay to detect α-1,3-glucan in Aspergillus hyphae and conidia without prior purification. Soluble α-1,3-glucan was substantially released by major Aspergillus species, as indicated by results of a sandwich ELISA-like assay with AglKA mutants. These findings suggest that soluble α-1,3-glucan has potential as a complementary diagnostic biomarker for aspergillosis.
|
|
Scooped by
mhryu@live.com
October 26, 9:56 AM
|
Drug development requires evidence integration across biological scales and modalities, but relevant tools are fragmented. We introduce the Virtual Biotech, an organization of artificial intelligence (AI) agents modeled on a drug-development company, with agentic divisions spanning target discovery, safety assessment, modality selection, and clinical development. We demonstrate its utility at three drug-development decision points. First, more than 37,000 agents annotated outcomes from 55,984 trials and found that drugs targeting cell type–specific genes were 48% more likely to reach market with 32% fewer adverse events. Second, it integrated multimodal evidence to propose a therapeutic strategy in lung cancer. Third, it analyzed a terminated ulcerative colitis trial and inferred potential mechanisms of failure. These results demonstrate that human-guided multi-agent systems can conduct transparent, multiscale analyses to inform therapeutic-development decisions.
|
|
Scooped by
mhryu@live.com
October 25, 4:45 PM
|
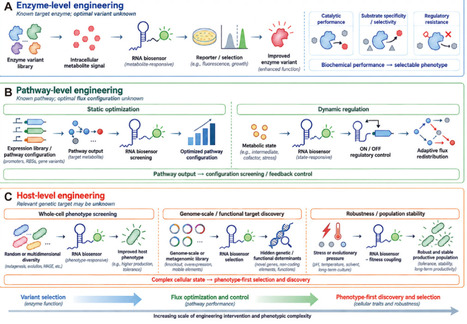
Microbial cell factory development requires iterative optimization of enzymes, pathway fluxes, and cell traits to achieve efficient and robust production of target chemicals. However, the complexity of intracellular metabolic networks often limits predictable identification and control of engineering targets. Genetically encoded metabolite-responsive RNA biosensors based on aptamer recognition and riboswitch- or ribozyme-mediated regulation have emerged as versatile tools for linking intracellular metabolite levels to measurable or selectable outputs. Their rapid signal transduction, compact genetic architecture, and low metabolic burden make them attractive for high-throughput screening and dynamic regulation. This Review adopts a hierarchical engineering framework that examines RNA biosensor applications across progressively broader levels, from enzyme engineering to pathway-level regulation and host-level cellular trait engineering. We further discuss their molecular organization and technological evolution, including ligand recognition, regulatory coupling, sensor tuning, and computational approaches. Finally, challenges associated with sensor robustness, host dependency, scalability, and translation into production-relevant phenotypes are discussed together with opportunities in cell-free characterization and data-driven design. This hierarchical perspective highlights RNA biosensors as engineering interfaces connecting intracellular sensing with interventions across multiple scales of microbial cell factory engineering.
|
|
Scooped by
mhryu@live.com
October 25, 1:01 PM
|
Bacterial transcription elongation has been investigated most thoroughly for the model bacterium E. coli. The E. coli elongation factor NusG associates through its N-terminal domain with the transcription elongation complex (TEC), while its C-terminal domain forms mutually exclusive interactions with either ribosomal protein S10 or Rho termination factor. The E. coli NusG:S10 complex bridges the TEC with a pioneering ribosome for coupling of transcription and translation. NusG also participates in antitermination complexes (ATC) that inhibit Rho-dependent termination and increase transcription of rRNA operons. A characteristic sequence in the nascent rrn RNA, called boxA, loads E. coli NusB:S10 onto the NusG-bound TEC, leading to the formation of the rrn ATC. However, these findings may not extend to all bacteria. Rho-dependent termination is less important in gram-positive bacteria, including some that do not encode Rho, and transcription and translation remain uncoupled in Bacillus subtilis and many other gram-positive bacteria. It is therefore unclear whether the interaction network for E. coli elongation factors is conserved in these organisms. We identified boxA-like sequences upstream of 16S and 23S genes in Bacillus species and found that they associate directly with NusB. We also found that B. subtilis S10 associates with both NusB and NusG, and that Rho can also associate with NusG. Bioinformatic analyses revealed conservation of interaction interface residues across multiple phyla. Together, these data demonstrate that the core interaction network of bacterial elongation factors is broadly conserved across diverse bacteria, despite differences in how these interactions function in individual species.
|