Your new post is loading...

|
Scooped by
mhryu@live.com
Today, 12:11 AM
|
Triacylglycerols (TAGs) are structurally diverse lipids whose functions are dictated by acyl composition, chain-length distribution, and sn-positional architecture. Microbial TAG production offers a sustainable route to bulk oils and high-value specialty lipids, yet the field has shifted from maximizing total lipid titers to precise control of TAG molecular structure. Acyltransferases (ATs) serve as key enzymatic nodes governing acyl-chain entry, positional incorporation, terminal TAG formation, and lipid droplet biogenesis. This review systematically covers five core AT families (GPAT, AGPAT, DGAT, WS/DGAT, PDAT) across bacteria, yeasts, fungi, and microalgae, highlighting their conserved catalytic motifs, membrane topology, substrate selectivity, and regulatory networks. We discuss engineering strategies including AI-assisted design, enzyme engineering, gene overexpression, metabolic rewiring, fermentation optimization, and multiomics-guided regulation, focusing on producing high-value structured TAGs such as human milk fat substitutes and very-long-chain TAGs. Future advances require synergistic integration of AT mechanisms, acyl-CoA supply, lipid droplet engineering, and scalable bioprocessing.
|
|
Scooped by
mhryu@live.com
Today, 12:01 AM
|
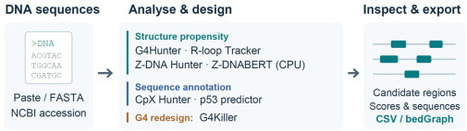
Local non-B DNA structures and R-loops are associated with genome regulation and stability. CpX islands and p53 response elements provide complementary sequence annotations. Exploring these features often requires separate tools and repeated sequence submission. DNA Analyser web server integrates G4Hunter, G4Killer, R-loop Tracker, Z-DNA Hunter, pretrained Z-DNABERT models running on CPUs, CpX Hunter and a p53-binding predictor. Palindrome analyser is linked as a separate companion server. Inputs include plain-text or FASTA upload, pasted sequences, multiple-sequence workflows and NCBI retrieval. Outputs include analysis settings, sortable regions, interactive graphics and module-specific exports. Guest and registered users have access to the same analytical functions. A shared sequence workspace supports examination of structural propensity, nucleotide composition and potential regulatory elements. Predictions identify candidates for further investigation; they do not demonstrate structure formation or biological function in vivo. Integrated access reduces repeated sequence handling and helps researchers explore complementary features of the same genomic region. DNA Analyser is freely accessible through HTTPS without identity registration at https://bioinformatics.ibp.cz/#/.
|
|
Scooped by
mhryu@live.com
November 2, 11:39 PM
|
The Min system disassembles FtsZ-rings after septation in Bacillus subtilis and is localized to the nascent division plane and cell poles by the protein MinJ. The N-terminal region of MinJ contains transmembrane segments while the C-terminal region contains a PDZ domain, but its membrane topology and functional domains are poorly understood. Here, we empirically tested competing topology models and found that MinJ is a nine-pass transmembrane protein with an extracellular N terminus and a cytoplasmic C terminal PDZ domain. Deletion of the PDZ domain resembled a MinJ null mutation but retained polar localization and interaction with both MinD and DivIVA. Deletion of transmembrane segments 6 and 7 abolished polar localization and interaction with MinD and DivIVA but conferred a hyper-minicell phenotype that was additive in the absence of MinD. Structural prediction by AlphaFold3 suggests that segments 6 and 7 may constitute an unusual transmembrane β-sheet, making MinJ perhaps the first of its kind to have such a secondary structure in the plasma membrane. Finally, phylogenetic analyses and structural comparison showed that MinJ sequence and structure are highly conserved within the Firmicutes and tightly co-conserved with MinD and DivIVA with which it interacts. Our work clarifies the membrane topology and functional organization of MinJ and supports models in which MinJ contributes to bacterial cell division through mechanisms beyond canonical Min system regulation.
|
|
Scooped by
mhryu@live.com
November 2, 11:09 PM
|
Research on plant viruses depends on taxonomy, nucleic acid sequences, host and disease records, molecular targets, and antiviral assays. These data are distributed across separate resources, making integrated retrieval and comparison difficult. PlantVirDisConDB (https://dpai.ccnu.edu.cn/PVDCDB) is freely accessible without login or registration and links these data through curated plant virus records. At the July 2026 reporting date, it comprised, in round numbers, 5000 virus and subviral agent records and 38 000 sequence accessions. It also included approximately1900 hosts, 9000 virus–host associations, 4800 disease names, 5000 structure records, and 25 000 small molecules. Direct assay records for plant viruses are distinguished from general antiviral background data; experimental and predicted structures, and measured activities and model outputs, are also labelled separately. Linked record pages support retrieval across these data types, access to individual sequence records, target searches, and molecular similarity searches. An activity prediction module ranks candidate molecule–virus pairs with applicability warnings and does not imply experimental or field efficacy. PlantVirDisConDB links viral nucleic acid entities to hosts, phenotypes, targets, and antiviral information and is updated through continuing curation and user feedback.
|
|
Scooped by
mhryu@live.com
November 2, 11:00 PM
|
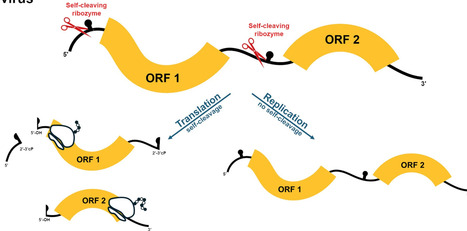
Small self-cleaving ribozymes are catalytic RNAs discovered in viroid-like agents, which are replicating circular RNAs (circRNAs) postulated as relics of a prebiotic RNA world. In the last decade, however, small ribozymes have also been detected across the tree of life, from bacterial to human genomes, and more recently, in unusual circRNA viruses. Here we report the conserved occurrence of diverse small ribozymes within the linear genomes of typical single- and double-stranded RNA viruses infecting fungi and plants. We identified type I hammerhead ribozymes in the 5′-UTRs of chrysovirids and fusarivirids, displaying self-cleaving activity in vitro and in vivo. Similar hammerhead, as well as hepatitis delta and twister ribozymes, occur in diverse megabirna-, hypo-, fusagra-, toti-, or tombus-like viruses. The ribozymes appear as isolated motifs within the UTRs or as tandem pairs that encompass small RNA segments (186–399 nt) resembling Zetavirus-like sequences. In vivo characterization of the 5′-UTR from a fungal chrysovirus revealed that its RNA self-cleaving activity is essential for protein translation initiation. Analogous experiments in plants with diverse ribozyme motifs confirmed that self-cleaving activity alone can induce cap-independent translation. We conclude that RNA self-cleaving activity, historically linked to the rolling circle replication of viroid-like circRNAs, appears to be co-opted by some linear RNA viruses for translational roles.
|
|
Scooped by
mhryu@live.com
November 2, 10:48 PM
|
InterPro (https://www.ebi.ac.uk/interpro) is a freely accessible resource for the classification of protein sequences. It integrates predictive models, known as signatures, from multiple member databases to classify sequences into families and to predict the presence of domains and functionally important sites. The InterPro database provides annotations for hundreds of millions of sequences, ensuring extensive coverage of UniProtKB, the standard repository of protein sequences, and includes mapping to several other major resources, such as Gene Ontology, the Protein Data Bank in Europe (PDBe), and the AlphaFold Protein Structure Database. In this publication we report on the status of InterPro (version 110.0), detailing new developments in the database, its associated web interface, and software. Notable updates include InterPro-N, a deep-learning method that increases sequence coverage of UniProtKB to over 90%; the transition from InterProScan 5 to the completely re-engineered InterProScan 6; the integration of structure-based domain classifications and predicted structures from AlphaFold; a redesigned protein viewer offering a concise summary view; and a new Model Context Protocol (MCP) server that allows AI assistants to query InterPro programmatically. Over the past two years, 9484 new InterPro entries have been created, bringing the total to 54 922. InterPro data, software and tools are freely available.
|
|
Scooped by
mhryu@live.com
November 2, 10:25 PM
|
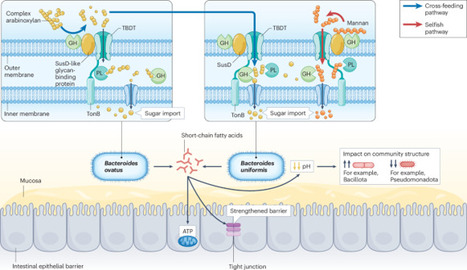
Prebiotics and fermentable fibre modulate gut microbiota composition and function in ways considered beneficial to health. However, both microbiota and clinical responses can vary widely among individuals, which reduces their efficacy as dietary interventions across populations and thus represents a key challenge for the field. In this Review, we discuss potential reasons for the individualized responses to prebiotics and putative prebiotic fibres and how this variability influences interactions among gut microbial species as well as between microorganisms and fibre structures. We further describe strategies for predicting and optimizing responses to prebiotic and putative prebiotic fibre treatments. Specifically, we highlight methods for targeted and predictable individual responses using systems biology, mechanistic modelling and machine learning approaches. We also consider how the physicochemical structures of fermentable fibre influence similarity in gut microbial responses. By integrating this knowledge, solutions are proposed to overcome inter-individual variability and improve the clinical efficacy and utility of prebiotic fibres. Prebiotics and dietary fibre show highly individualized effects on gut microbiota and clinical outcomes, challenging their consistent effectiveness across populations. This Review examines the drivers of this variability, presents predictive approaches and discusses strategies to optimize prebiotic responses across individuals.
|
|
Scooped by
mhryu@live.com
November 2, 10:15 PM
|
Regulation of RNA pools in bacteria is a fundamentally important process to allow for survival and adaptation to changing environments. RNA degradation is an important piece of this regulation carried out, in part, by the core RNA degradosome, which is a multiprotein complex composed of ribonucleases (RNases), RNA helicases, and sometimes central carbon metabolic enzymes. In this review, we highlight the diversity in degradosome composition across all phyla of bacteria and the differences between stable degradosomes and the more recently recognized transient degradosome-like networks (DLNs). Additionally, we describe advancements in understanding the RNA targets and subcellular organization of degradosomes/DLNs. Importantly, we discuss the roles of RNA degradosomes/DLNs during physiologically relevant stress as well as virulence. Our review reveals the great diversity among degradosomes/DLNs and underscores the need to study a range of bacterial species in this field beyond traditional model systems.
|
|
Scooped by
mhryu@live.com
November 2, 4:59 PM
|
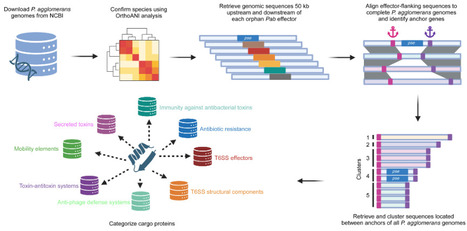
Gram-negative bacteria deploy type VI secretion systems (T6SSs) to mediate interbacterial competition. Although numerous T6SS effectors have been identified, their pan-genomic repertoires and evolutionary dynamics remain poorly understood. Here, we combine proteomics and comparative genomics to map the T6SS effector landscape across Pantoea agglomerans, a species that includes pathogenic and beneficial strains. We uncover an extensive pan-genomic arsenal in which most effectors are encoded outside the T6SS gene cluster, within dynamic hotspots distributed across the chromosome and megaplasmids. Analysis of these hotspots reveals combinatorial arrangements of shuffled genetic cargo. Remarkably, these loci act as versatile “genomic armories” that co-localize offensive antibacterial weapons with protective anti-phage defense systems. By investigating uncharacterized genes within these variable regions, we discovered and validated a novel T6SS effector and a previously unknown anti-phage defense system, named Juno. Collectively, our findings demonstrate that bacterial warfare arsenals are highly modular and reside in dynamic genomic hubs that alternate or combine interbacterial aggression with viral defense. This evolutionary association reveals a functional blurring between offensive and defensive strategies within the bacterial accessory genome.
|
|
Scooped by
mhryu@live.com
November 2, 2:40 PM
|
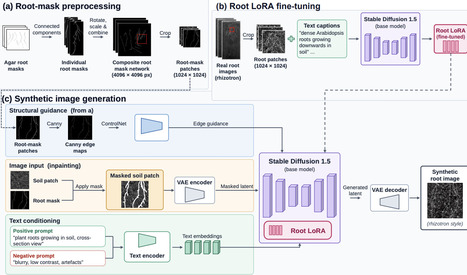
Rhizotrons allow root system architecture to be studied non-destructively in soil. However, automated analysis of rhizotron images remains difficult: roots have low contrast against soil, soil particles resemble fine roots, and deep learning models need many manually annotated images that are slow and subjective to produce. Synthetic images could provide paired images and annotations at scale, but rhizotron images are largely absent from the data used to train generative models. We built a pipeline combining Low-Rank Adaptation (LoRA), ControlNet and inpainting to generate synthetic rhizotron images with paired root masks. We compared training on synthetic data only, real data only, and synthetic pretraining followed by fine-tuning on real images, using three segmentation models: nnU-Net v2, YOLO26 and Mask2Former. Synthetic-only training reached a Dice score of up to 0.60. Synthetic pretraining followed by fine-tuning on the full real training set (two annotated rhizotron images) reached 0.80, and nnU-Net v2 and Mask2Former reached 0.62 with only two annotated image patches containing visible roots. When real annotations were limited, pretraining also improved segmentation of unseen crops, including lettuce, barley, wheat, maize, tomato, cucumber, French bean and field bean. We also introduced a Soft Dice score that compares predictions with probabilistic consensus maps from seven independent annotators, accounting for annotator disagreement. Models matched average human agreement on low-ambiguity patches but remained below it on high-ambiguity patches. In conclusion, diffusion-generated images can complement real annotations and help scale root segmentation, although their effect on downstream root trait measurements still needs to be validated.
|
|
Scooped by
mhryu@live.com
November 2, 2:19 PM
|
Chemical modifications of transfer RNAs (tRNAs) are crucial for tRNA stability, codon decoding, translational fidelity, and tRNA-derived small RNA (tsRNA) biogenesis. Changes in these modifications are associated with stress responses, physiological regulation, and human disease, underscoring the need to integrate modification information with experimental evidence and biological context. We previously established tModBase, a web resource to organize and explore tRNA modification-related data. Its first release integrated modification sites, high-throughput sequencing-derived signals, and condition-dependent changes. Since then, tRNA profiling has expanded through modification-specific and direct RNA sequencing strategies, with rapidly growing datasets across species and conditions. Here, we present tModBase v2.0 (http://www.tmodbase2.com/), containing 528 datasets across 23 species, 40 sequencing and library-preparation methods, and 42 modification types. It includes 68 third-generation and 210 modification-specific sequencing datasets, extending coverage of direct-RNA and modification-specific approaches. tModBase v2.0 further integrates sequencing-derived signals, condition-dependent information, and biological annotations linking modifications with enzymes, genetic variants, tsRNAs, diseases, and expression profiles. The LLM- and retrieval-augmented generation-powered assistant tModBot enables natural-language exploration across database modules while grounding responses in retrieved tModBase evidence. tModBase v2.0 therefore provides an expanded resource for investigating the diversity, dynamics, and biological context of tRNA modifications.
|
|
Scooped by
mhryu@live.com
November 2, 2:08 PM
|
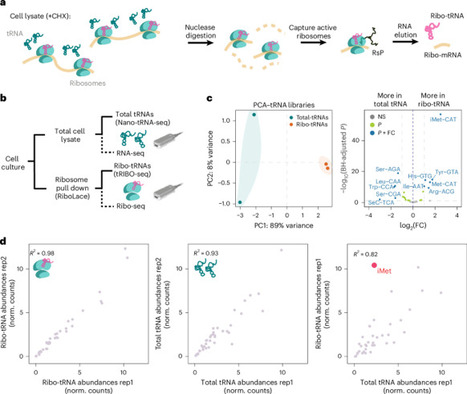
During translation, transfer RNAs (tRNAs) deliver specific amino acids to the ribosome in a coordinated manner with the sequence encoded by the messenger RNA. Despite their central role in protein synthesis, their precise contribution to the modulation of translation remains poorly understood, primarily due to lack of methods to characterize tRNA abundances and their modifications from actively translating ribosomes. Here we develop tRIBO-seq, a simple and robust nanopore-based method to selectively capture ribosome-associated native tRNA populations (ribo-tRNAs) from actively translating ribosomes, providing tRNA abundance, modification and fragmentation information from a single experiment. Using tRIBO-seq, we find that ribo-tRNAs, but often not otal tRNAs, are significantly altered on stress. Notably, we find that tRNAome alterations strongly vary depending on the stress type; while viral infection and leucine deprivation leads to changes in ribo-tRNA abundances, methionine starvation causes a dramatic loss of methyl-based tRNA modifications. By contrast, we find that arsenite exposure does not alter tRNA abundances nor modification patterns, but rather causes major fragmentation events in selected subsets of ribo-tRNAs. Altogether, tRIBO-seq offers a robust and reproducible approach to map the full tRNA landscape—capturing tRNA abundance, modification and fragmentation patterns—across both total and actively translating tRNA populations, revealing the dynamics of the tRNAome with unprecedented resolution, in a single experiment. tRIBO-seq distinguishes between ribosome-associated tRNAs and total tRNAs using nanopore sequencing, thus revealing their potentially distinct abundance, modification and fragmentation patterns in various conditions.
|
|
Scooped by
mhryu@live.com
November 1, 1:30 PM
|
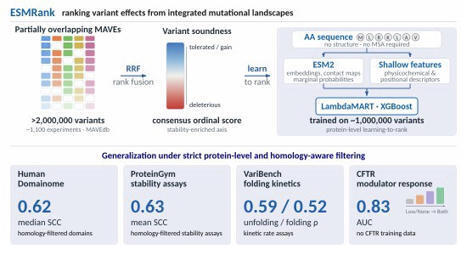
Predicting the functional effects of missense variants is limited both by predictor performance and by the lack of principled strategies to integrate heterogeneous multiplexed assays of variant effect (MAVEs), including deep mutational scanning, into transferable sequence-function models. Here, we show that redundancy among partially overlapping deep mutational scanning experiments, often treated as noise, yields a consensus landscape of mutational constraint. We introduce “variant soundness”, an overlap-aware rank-fusion score that uses cross-experiment consistency to derive an assay-agnostic ordering of mutational tolerance within proteins. Applied to ~1100 MAVEs spanning over two million missense variants, this approach reveals a mutational landscape enriched for structural stability constraints. Guided by this integrated signal, we develop ESMRank, a sequence-based learning-to-rank predictor combining ESM2 representations with physicochemical descriptors. Under strict protein-level partitioning, ESMRank outperforms widely used predictors across abundance-, folding-, and stability-related assays in ProteinGym and Domainome. Predicted deleterious variants are enriched for ClinVar pathogenicity and, in CFTR, correlate with folding efficiency, channel activity, and pharmacological responsiveness. Together, these results turn assay redundancy into a scalable resource for interpretable missense variant prediction.
|
|
|
Scooped by
mhryu@live.com
Today, 12:07 AM
|
Ribosomes are capable of incorporating a wide array of natural and unnatural monomers into growing polymer chains, but can be stalled by monomers with constrained or non-natural backbones. Here we evaluate whether monomer-dependent ribosome stalling can be alleviated by structure-guided mutations to 23S rRNA within the exit tunnel. E. coli ribosomes harboring an A2062U mutation are as active as wild type (WT) ribosomes when translating nonproline sequences and up to 10-fold more active when translating sequences containing three or four consecutive proline residues. High-resolution cryo-EM structures of WT and A2062U mutant ribosomes containing a polyproline nascent chain reveal that the A2062U mutation relieves an exit tunnel constriction to better accommodate a conformationally restricted peptide chain. A2062U mutant ribosomes also improve translation of sequences containing multiple, consecutive β2-hydroxy acids. These results provide a mechanistic basis for engineering the E. coli ribosome for improved translation of genetically encoded polymers with novel backbones.
|
|
Scooped by
mhryu@live.com
November 2, 11:58 PM
|
Carbon catabolite repression (CCR) enables fungi to preferentially utilize favorable carbon sources through global transcriptional control. In filamentous fungi, CCR is classically attributed to the C2H2 zinc-finger repressor Mig1/CreA; however, residual repression following Mig1 disruption suggests additional regulatory layers in Talaromyces pinophilus (previously called Penicillium funiculosum NCIM1228). Here, we identify Mig3, a previously uncharacterized, Eurotiales-specific C2H2 transcription factor that functions redundantly with Mig1 in CCR. Mig3 contains conserved N-terminal zinc-finger motifs and a fungal transcription factor middle homology region and binds canonical Mig1 response elements with higher DNA affinity. Genetic analyses reveal that simultaneous loss of Mig1 and Mig3 is synthetically lethal, indicating an essential shared function beyond carbon repression. Integrative transcriptomic, chromatin immunoprecipitation sequencing, and proteomic analyses demonstrate that Mig1 and Mig3 directly regulate genes encoding mitochondrial and ribosomal components, including key factors involved in oxidative phosphorylation, while repressing genes required for alternative carbon metabolism. Loss of either repressor compromises expression of respiratory and ribosomal genes and confers hypersensitivity to mitochondrial and ribosomal inhibitors. In addition, both repressors physically associate with mitochondrial, ribosomal, and central metabolic proteins, suggesting coordination of transcriptional and posttranscriptional regulatory mechanisms. Together, our findings redefine fungal catabolite repressors as metabolic gatekeepers that couple CCR to mitochondrial and ribosome biogenesis, thereby controlling the metabolic switch between core cellular growth processes and enzyme secretion.
|
|
Scooped by
mhryu@live.com
November 2, 11:34 PM
|
Cyclic di-GMP is ubiquitous in Bacteria, including members of the deepest branching phyla, but has not yet been detected in Archaea. Thus, whether cyclic di-GMP was present as a signaling nucleotide in the last universal common ancestor (LUCA) of Bacteria and Archaea remains unknown. In this work, bioinformatic analyses and structural modelling identified GGDEF domain proteins in archaeal isolates and encoded by metagenomes of confirmed archaeal origin. In particular, in bacterial model organisms, phenotypic and in vivo assays, in combination with catalytic mutants, suggest that selected archaeal GGDEF domain proteins possess diguanylate cyclase activity. These include the complex RECS-PAS/PAC-PocR-GGDEF-HD-GYP domain protein of Methanocella arvoryzae MRE50, a member of the Stenosarchaea order Methanocellales. While cyclic di-GMP signaling proteins are ubiquitous in Bacteria, their presence seems to be more sporadic in Archaea. It is currently unclear whether cyclic di-GMP signaling proteins have been lost in some lineages, secondarily introduced by horizontal gene transfer into others, or whether both scenarios have occurred.
|
|
Scooped by
mhryu@live.com
November 2, 11:02 PM
|
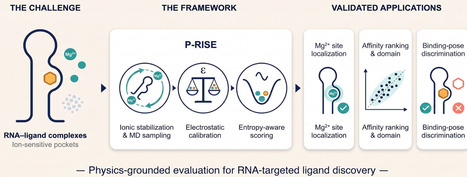
RNA-targeted small-molecule discovery is challenged by the scarcity of experimentally characterized RNA–ligand complexes and by the limited transferability of current computational approaches across chemically diverse systems. Here we present P-RISE, a physics-grounded framework for RNA–ligand binding prediction, and use it to identify the physical determinants underlying reliable performance. Systematic evaluation of force fields, ionic environments, dielectric treatments, and entropy corrections reveals three coupled requirements: preservation of RNA-binding pocket integrity under ion-sensitive conditions; an effective electrostatic error cancellation regime enabled by an elevated internal dielectric constant; and an empirically observed coupling between entropy correction and solvent modeling. Integrating these features, P-RISE provides stable affinity ranking, physics-grounded delineation of its physicochemical applicability domain, accurate metal ion site localization, and improved binding pose discrimination relative to established RNA docking and scoring approaches. Crucially, benchmarking against AlphaFold3 reveals that co-folding models, optimized for structure generation rather than energetic ranking, benefit from an explicit physics-based evaluation layer. Furthermore, diverse machine-learning comparisons demonstrate that purely data-driven methods lack stability and generalization in this data-poor regime. Ultimately, P-RISE provides a mechanistic understanding of RNA–ligand modeling, serving as a principled physical baseline that defines reliable prediction boundaries, and guides future data-driven integration.
|
|
Scooped by
mhryu@live.com
November 2, 10:54 PM
|
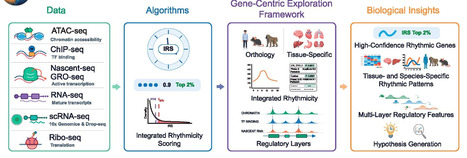
The circadian clock orchestrates daily physiological processes through coordinated regulation of clock-controlled gene expression across multiple molecular layers. However, systematic characterization of this multilayered rhythmic regulation remains challenging because relevant information is distributed across independent datasets and rhythmicity is evaluated using diverse analytical approaches. Here, we developed CircaVal, a gene-centric multi-omics platform for the integrated exploration and interpretation of circadian regulatory features in humans, mice, and baboons. To support this framework, CircaVal processes public datasets using standardized, data-type-specific pipelines, and gene rhythmicity is integrated with tissue-specific expression, cross-species orthology, functional annotations, and multi-omics regulatory features. CircaVal further introduces an integrated rhythmicity score (IRS), which combines concordance across multiple rhythm-detection methods with reproducibility across independent datasets to provide a quantitative basis for prioritizing candidate rhythmic genes. The platform enables users to examine gene rhythmicity across datasets, identify tissue-enriched rhythmic genes, compare rhythmicity across species, and explore associated regulatory features. Additional functions include interactive gene-centric exploration, genome-browser visualization, rhythmicity analysis of user-uploaded time-series data, and programmatic data access. Together, these capabilities provide an integrated framework for rhythmic gene prioritization and gene-level interpretation of circadian regulatory features across tissues, species, datasets, and omics data types. CircaVal is freely available at https://CircaVal.com.
|
|
Scooped by
mhryu@live.com
November 2, 10:33 PM
|
Genome expansion and contraction are driven by transposable element activity, but the underlying dynamics remain enigmatic due to a lack of historical records tracing these changes. Here, we present PrinTE, a forward-time simulator of whole-genome sequences with customizable transposon dynamics for identifying the evolutionary parameters most consistent with an observed genome. Across simulations spanning four orders of magnitude, PrinTE recovers transposon insertion and deletion rates with less than 6% error. We demonstrate PrinTE on Arabidopsis and the fungal subdivision Pucciniomycotina, including myrtle rust (Austropuccinia psidii), which expanded its genome size to 1,018 Mb through transposon amplifications. Our simulations show that recombination-based removal of LTR retrotransposons alone cannot prevent genome obesity, and that preventing their invasion in the first place is more effective. We hypothesize that A. psidii might have experienced a prolonged expansion phase followed by a potent and ongoing period of contraction. The authors present PrinTE, a freely available simulator that evolves genomes forward in time to reveal how transposable elements drive genome expansion and contraction, and use it to test hypotheses about genome size evolution in fungi and plants.
|
|
Scooped by
mhryu@live.com
November 2, 10:19 PM
|
Bacteriophages cause active host cell lysis to terminate their infection and release progeny into the environment. However, some phages have systems to delay their lysis, and thereby increase progeny yield, in specific conditions: a phenomenon called lysis inhibition (LIN). Two dissimilar phages of E. coli are known to exhibit LIN: T4 and N4. In T4, a multi-protein mechanism stalls lysis and maintains the LIN state in response to superinfection in a high phage population density. However, the lysis proteins responsible for T4 lysis and LIN are not conserved with phage N4. In this study, we characterize the phage N4 proteins involved in lysis by molecular and genetic means. We define the functions of the minimal gene set required for lysis through heterologous expression and complementation. Furthermore, by sequence comparison with a selected mutant library that does not induce LIN, we have identified genomic regions both within and outside the lysis cassette involved in N4 LIN. We propose a model where N4 lysis proteins that execute rapid N4 lysis can be regulated to induce LIN. Despite the lack of conservation with T4 components, our study suggests that direct modulation of lysis initiation may be common and provides a springboard for identifying similar mechanisms in other phages.
|
|
Scooped by
mhryu@live.com
November 2, 9:47 PM
|
Whether human-associated environments drive adaptive genome evolution in gut commensal bacteria remains largely unknown. Here, we investigate how genomic adaptation in gut bacteria differs between industrialized and non-industrialized human populations. We generated a collection of isolate genomes spanning diverse host geographies, lifestyles, species, and strains. We first found that, compared with metagenome-assembled genomes (MAGs), paired isolate genomes recover more functional elements and signals of horizontal gene transfer (HGT). Leveraging isolate genomes from multiple species, we find that strains from industrialized hosts experience an expansion of proteome size and harbor greater pangenome fluidity, driven by recent HGT events. Gene- and variant-level analyses reveal convergent patterns of lifestyle-specific adaptation in functions that are critical for ecological adaptation, such as the stress response, cell-envelope remodeling, and central metabolism. Our results demonstrate that industrialization drives convergent genome evolution in gut bacteria, providing a framework for understanding the mechanisms of microbial adaptation to rapidly changing human environments.
|
|
Scooped by
mhryu@live.com
November 2, 2:54 PM
|
mRNA decay is a key post-transcriptional regulatory mechanism that fine-tunes plant development and stress adaptation through dynamic mRNA stability control, bridging fundamental biology and crop improvement. Current knowledge of mRNA decay mechanisms in plants, largely derived from Arabidopsis, is poorly generalizable across plant lineages owing to insufficient exploration of other species. Recent advances in high-throughput sequencing have accelerated the discovery of mRNA decay mechanisms. Here, we systematically illustrate its core molecular mechanisms alongside breakthrough advances. We further dissect evolutionary characteristics of highly conserved core components and lineage-specific adaptive variations across eukaryotes. Notably, conserved since the last eukaryotic common ancestor (LECA), this machinery reflects a complex ancestral eukaryote and provides high-resolution phylogenetic markers for reconstructing eukaryotic origins. We also clarify the essential biological roles of mRNA decay in developmental modulation and stress responses. Finally, we propose precision breeding strategies based on mRNA stability regulation to develop high-yielding, climate-resilient crops. This review integrates up-to-date mechanistic evidence and comparative evolutionary perspectives, consolidates consensus findings and sorts out inconsistent research outcomes, and seeks to enrich the fundamental biological understanding of plant mRNA stability modulation.
|
|
Scooped by
mhryu@live.com
November 2, 2:22 PM
|
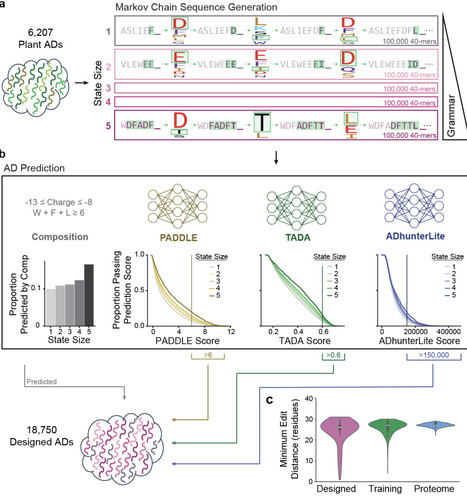
Artificial intelligence has accelerated the design of structured proteins, but it remains difficult to design functional intrinsically disordered proteins because of weak structural constraints and poorly defined sequence-to-function relationships. Activation domains (ADs), transcription factor regions that recruit coactivators, are an excellent test case for the de novo design of intrinsically disordered sequences. ADs are one of the oldest groups of functional intrinsically disordered sequences and designed ADs have applications in synthetic biology, biotechnology, and agriculture. We computationally generated 500,000 candidate sequences that resembled known ADs and predicted AD function with extant machine learning models, including three neural networks. From high-scoring sequences, we selected 18,750 for experimental validation in yeast. Surprisingly, >90% of the 16,770 well-measured sequences function as ADs. Sequences predicted to be active by multiple models were stronger, motivating development of a fast and accurate consensus AD predictor, MADRIGAL. A number of our designed ADs retain functionality across fungi, plants, and human cells. This work illustrates a generalizable paradigm for incorporating sequence-to-function models into the design loop to efficiently generate functional intrinsically disordered sequences.
|
|
Scooped by
mhryu@live.com
November 2, 2:14 PM
|
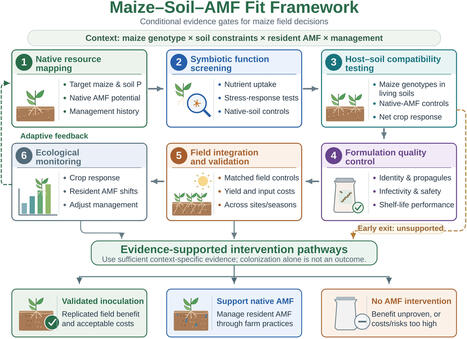
Arbuscular mycorrhizal fungi (AMF) can improve nutrient acquisition and stress responses in maize, yet inoculation benefits remain inconsistent across fields. Root colonization alone does not establish effective nutrient transfer or net crop benefit. This critical narrative review examines maize-associated AMF diversity, arbuscule-mediated exchange, host genotype effects, phosphorus availability, stress responses, rhizosphere and hyphosphere interactions, inoculant quality, and field evidence. We define crop-adapted AMF by demonstrated function in a specified maize–soil–management context, rather than fungal origin or colonization percentage alone. Drawing on mechanistic research and contrasting field outcomes, we propose a six-stage Maize–Soil–AMF Fit Framework linking native resource mapping, functional screening, compatibility tests, formulation quality, field integration, and ecological monitoring. The framework distinguishes practical agronomic evidence from advanced mechanistic measurements and permits three decisions: inoculate with a validated product, manage an effective native AMF network, or avoid intervention. It is a conceptual decision aid, not a validated predictive model. Reliable application requires replicated, genotype-aware field tests with appropriate native-AMF controls, prespecified crop outcomes, and transparent assessment of uncertainty and economic value.
|
|
Scooped by
mhryu@live.com
November 1, 11:26 PM
|
RNA foundation models offer a promising route to decoding the relationships between RNA sequence, structure and function, yet how model shapes the acquisition and organization of biological information remains poorly understood. Here we introduce Layer-Interleaved Mamba-Bidirectional Encoder for RNA (LIMBER), a hybrid foundation model integrating bidirectional self-attention with selective state-space modeling, pretrained on 40.5 million non-coding RNA sequences. Through task-specific fine-tuning, LIMBER achieves leading performance on secondary-structure prediction and non-coding RNA classification benchmarks, while demonstrating strong transferability to translation-related tasks and RNA--small-molecule interaction prediction. Beyond model development, we establish a unified, task-agnostic framework to systematically evaluate and interpret the biological knowledge intrinsically acquired by RNA foundation models. This framework validates LIMBER's strong capabilities in recovering RNA structures and predicting mutational effects, while uncovering a hierarchical, task-dependent organization of different biological information across model layers. By further systematically training and evaluating a broad panel of model variants spanning model capacity, training duration and dataset size, we uncover distinct scaling behaviors across structural, evolutionary and functional capabilities. Together, these findings establish LIMBER as a versatile RNA foundation model and provide broader insights into how architectural design, internal representations and scaling shape the learning of RNA sequence-structure-function relationships.
|