 Your new post is loading...

|
Scooped by
mhryu@live.com
Today, 11:16 AM
|
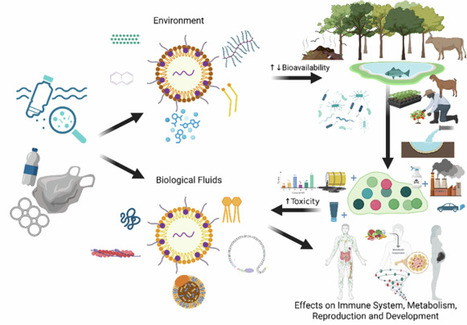
Recent data indicate plastics and associated chemicals pose risks to all forms of life - from plants, microbes, and animals to humans and their developing embryos. Plastics decompose over time into Micro and Nanoplastics (MNPs), which are present as particles or fibrils. MNPs are surrounded by other substances through hydrophobic and hydrophilic interactions, known as eco-coronas in the environment, and within living organisms as bio-coronas. We highlight key biological phenomena that may help us better understand the unique and complex impact of a Trojan horse-like exposure to the bio-corona’s cargo of MNPs. These could modify, enhance, or inhibit hormones and other active substances essential for homeostasis. The investigation of MNPs with bio-corona is of high public health relevance.
|
|
Scooped by
mhryu@live.com
Today, 10:44 AM
|
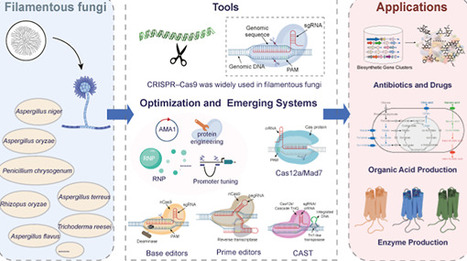
Filamentous fungi are important microbial cell factories for producing antibiotics, organic acids, enzymes, and other valuable products, with broad applications in food, agriculture, and medicine. However, inefficient and imprecise genome editing remains a major bottleneck limiting rational strain engineering. This review summarizes major genome-editing tools in filamentous fungi, including Cre-loxP, TALENs, and CRISPR–Cas systems, with emphasis on their mechanisms, advantages, and limitations. We highlight CRISPR–Cas9 as the predominant platform and discuss optimization strategies involving sgRNA design, engineered Cas9 variants, promoter engineering, AMA1-based replicative plasmids, and ribonucleoprotein delivery. Emerging technologies, including base editing, prime editing, Cas12a, and Mad7, are also discussed for their potential to broaden editing capabilities. Finally, we outline future perspectives focusing on extending the application of existing genome-editing systems in filamentous fungi and discovering novel genome-editing tools from large-scale omics data sets. This review will accelerate the development of filamentous fungi as versatile platforms for biomanufacturing.
|
|
Scooped by
mhryu@live.com
Today, 10:18 AM
|
This book explores recent, fully updated techniques involving computational approaches to the study of synthetic biology.
|
|
Scooped by
mhryu@live.com
Today, 10:03 AM
|
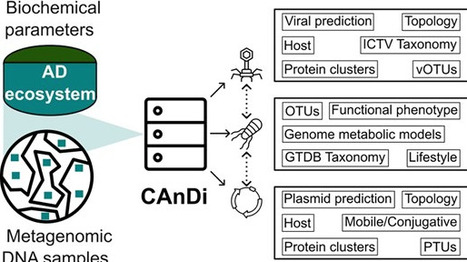
Methanogenic environments harbor complex prokaryotic consortia that drive the anaerobic conversion of organic matter into methane and carbon dioxide. Beyond being key to the global carbon cycle, such processes have been steered into powerful biotechnologies for energy production in bioreactors. Decoding the functional and taxonomic landscape of these communities requires comprehensive surveys, including bacteriophages and plasmids, which, however, remain vastly underrepresented in current databases. Here, we present the microbial Catalogue of Anaerobic Digestion (CAnDi), a database comprising 36 480 prokaryotic genomes spanning 11 149 species recovered from 1256 metagenomic samples collected across bioreactors worldwide. The reconstructed metagenomes also encode ∼1.9 million viral and over 130 000 plasmid sequences. Identity clustering revealed ∼536 000 candidate viral species, of which 85% are novel relative to existing databases, as well as over 15 000 unique plasmids. Clusters of viral and plasmid proteins were generated de novo, totalling 1 721 182 and 123 813 distinct protein families, respectively. Together, these resources substantially advance previous systematic approaches to characterize anaerobic digestion microbiomes, providing an expanded foundation for investigating the ecological and evolutionary roles of the virome and plasmidome in methane-producing ecosystems. CAnDi is accessible via https://www.candi-db.org/.
|
|
Scooped by
mhryu@live.com
October 31, 5:39 PM
|
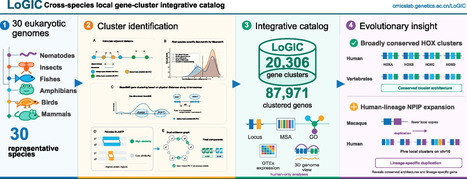
Homologous genes, especially those sharing close genomic locations and forming gene clusters, often have compensatory roles, therefore pose remarkable challenges for deciphering the functions and relationships of these genes. A comprehensive database of local homologous gene clusters with multimodal information would greatly facilitate such research. Here, we present LoGIC (https://omicslab.genetics.ac.cn/LoGIC/), a Local Gene-cluster Integrative Catalog that includes 20 306 local gene clusters identified from 30 representative eukaryotic species. In addition to the basic genomic features of each gene cluster, LoGIC also allows users to examine the sequence similarity of gene members within a cluster, the functional preference of clustered genes within a species, and the cross-species conservation of gene clusters. Information of tissue-wide expression profile and relationship with chromatin Hi-C structure is also available for human gene clusters. Together, LoGIC can facilitate studies of tandem gene duplication, paralog functional divergence, lineage-specific gene-family expansion, and evolutionary conservation or remodelling of homologous gene clusters across-species.
|
|
Scooped by
mhryu@live.com
October 31, 5:05 PM
|
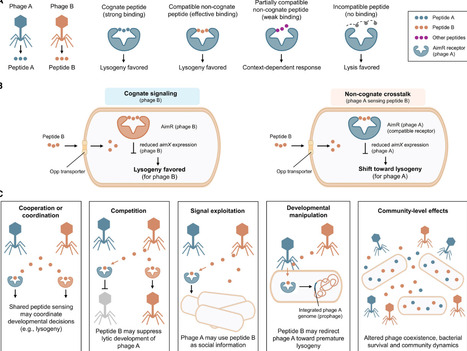
The arbitrium system has transformed our understanding of phage biology by demonstrating that temperate phages communicate through extracellular peptides to coordinate lysis-lysogeny decisions. Initially considered a highly specific signaling pathway restricted to individual phage lineages, arbitrium communication has now been shown to extend beyond lineage boundaries in some phage systems. Recent studies have shown that non-cognate arbitrium peptides can interact with heterologous receptors, providing evidence of inter-phage crosstalk. Here, we synthesize current knowledge of the molecular basis of arbitrium signaling, the structural determinants of peptide-receptor specificity, and the potential ecological and evolutionary consequences of inter-phage communication. We suggest that arbitrium crosstalk may shape phage ecology by mediating competitive and potentially cooperative interactions within shared signaling environments. We also discuss its potential uses in engineered phage systems, synthetic biology, and microbiome engineering. Collectively, the available evidence broadens the concept of viral communication beyond lineage-specific signaling, while the ecological significance and practical applications of arbitrium crosstalk remain to be established.
|
|
Scooped by
mhryu@live.com
October 31, 4:43 PM
|
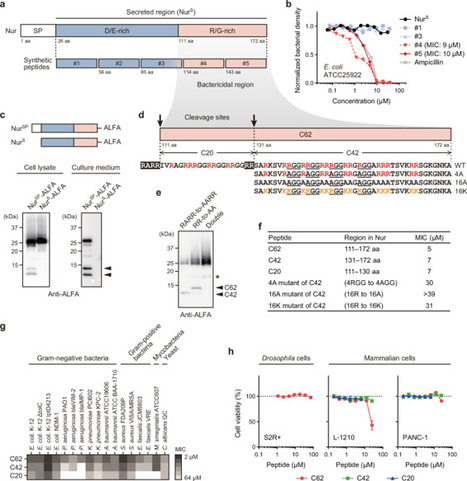
Antibiotic resistance is a global health threat requiring antimicrobials with alternative modes of action. Growing evidence indicates that bacteria organize key intracellular processes through biomolecular condensates and other forms of spatial organization, yet whether such spatial organization can be exploited as an antimicrobial target remains unclear. Here, we identify intrinsically disordered antimicrobial peptides, generated from the Drosophila sleep-inducing protein Nemuri, that inhibit bacterial growth by targeting ribosomal organization. Mechanistically, these peptides enter bacterial cells without overt membrane disruption and accumulate in ribosome-rich regions, where they bind broadly to RNA and ribosomal surfaces through multivalent interactions. This engagement remodels ribosome-rich regions into condensates with reduced ribosomal mobility, thereby suppressing global protein synthesis and distinguishing these peptides from canonical site-specific ribosome-targeting antibiotics. Furthermore, Nemuri-derived peptides exhibit broad-spectrum antimicrobial activity, including activity against drug-resistant pathogens, with low cytotoxicity toward Drosophila and mammalian cells. Together, our findings identify the organization and material dynamics of bacterial ribosomes as a biophysical vulnerability that can be exploited by antimicrobial peptides, revealing how a naturally evolved metazoan host-defense system turns intracellular organization itself into an antibacterial target. Nishinami et al. show that peptides from the sleep-inducing protein Nemuri, condense bacterial ribosomes and inhibit protein synthesis, revealing a biophysical antimicrobial strategy targeting intracellular organization.
|
|
Scooped by
mhryu@live.com
October 31, 4:12 PM
|
Sequence-only predictors can score RNAs without experimental structures, but continuously updated training pools can reabsorb benchmark chains. Test overlap and within-training redundancy are often handled together, although they affect evaluation differently. DUET combines a relational graph tower with two convolutional sequence towers built on frozen RNA language models. We removed 98 of 388 training and validation records reaching 80% identity to canonical test chains, retained 110 sequence-identical records, and isolated 115 homology components across folds. Across 10 paired seeds, DUET reached 0.240 +/- 0.013 MCC versus 0.192 +/- 0.031 for CoBRA-M3 on the same data (Delta = +0.047; Holm p = 0.0073), with parallel gains in AUC and AUPRC. DUET and GRASSP were statistically indistinguishable on external sets (0.246 versus 0.243 MCC). Real three-dimensional topology improved MCC by +0.037 over shuffled edges and by +0.042 over predicted secondary structure. Increasing the training pool from 80 to 290 records raised DUET by +0.135 MCC. Benchmark evaluation therefore requires separate controls for test overlap and within-training redundancy.
|
|
Scooped by
mhryu@live.com
October 30, 4:58 PM
|
Microbial ecosystems can now be measured across genomic, transcriptomic, proteomic, metabolomic, and environmental dimensions, yet their emergent functions remain difficult to predict and control. Artificial intelligence (AI) can integrate heterogeneous data, but predictive accuracy alone does not establish causality, transferability, or controllability. This review developed a five-layer framework: observe, infer, predict, design, and learn that connects microbial measurement to prospective intervention and experimental feedback. We critically synthesise evidence from sequence and protein learning, multi-omics integration, metabolic modelling, synthetic microbial communities, environmental biotechnology, and temporal forecasting. Recent primary studies illustrate progress in forecasting community trajectories, predicting microbial competition and designing consortia for pollutant degradation; they also reveal important boundaries between model performance and demonstrated ecosystem control. We examine risks arising from compositional data, information leakage, dependent observations, batch effects, uncertain calibration, sparse perturbation data, ecological instability, and evolutionary change. We propose operational criteria for ecosystem programmability and a staged validation pathway from controlled systems to field-relevant environments. Progress will depend on standardised context-rich data, hybrid AI–mechanistic models, prospective benchmarks, independent replication, and safety-constrained design.
|
|
Scooped by
mhryu@live.com
October 30, 4:45 PM
|
Anthropogenic nitrogen (N) enrichment profoundly influences the growth of N-fixing plants, but the drivers underlying their highly variable biomass responses remain poorly quantified. Through a meta-analysis of 2,110 paired observations across 76 N-fixing plant species from 121 experiments, we demonstrate that N enrichment increases N-fixing plant biomass by 14.2% on average, with responses ranging from −99.4% to 1301.3%. Intraspecific variability (26.9%; i.e., variation among individuals within species) and plant phylogeny (21.1%) represent substantial yet frequently overlooked sources of uncertainty in biomass responses of N-fixing plants to N enrichment, even though environmental conditions (climatic and edaphic factors) and experimental design (N enrichment rate and duration) account for a significant portion of biomass response variation. Intraspecific variability, phylogeny, and experimental design collectively explain a larger proportion of variance in root than in shoot biomass responses, whereas environmental conditions show the opposite trend. These results provide quantitative evidence that phylogeny and intraspecific variability are indispensable for accurately predicting the response of N-fixing plants to global change. Nitrogen enrichment alters the growth of nitrogen-fixing plants, but responses vary widely. This meta-analysis shows that phylogeny and intraspecific variation are major contributors to that variability.
|
|
Scooped by
mhryu@live.com
October 30, 4:37 PM
|
d-Allulose is a low-caloric natural sweetener and a promising alternative to d-sucrose and high-fructose corn syrup. Its current production relies on immobilized enzymes operating at approximately 60°C. In this research article, we developed a whole-cell process that converts d-glucose to d-allulose at 30°C, eliminating the need for enzyme purification and immobilization. To overcome inefficient d-glucose conversion to d-fructose at this temperature, we subjected a bacterial selection strain, whose growth was coupled to d-glucose isomerase activity, to adaptive laboratory evolution. This yielded improved d-glucose isomerase variants and mutations that strongly enhanced sugar uptake. Their integration into a highly engineered chassis strain expressing d-allulose 3-epimerase, together with another adaptive evolution experiment, enabled d-allulose yields of up to 19%, exceeding those obtained with immobilized enzymes at high temperatures. Together, our findings establish a strategy to overcome the limitations of a cell-free enzymatic process using a microbial whole-cell catalyst, offering alternative solutions for the food industry.
|
|
Scooped by
mhryu@live.com
October 30, 4:32 PM
|
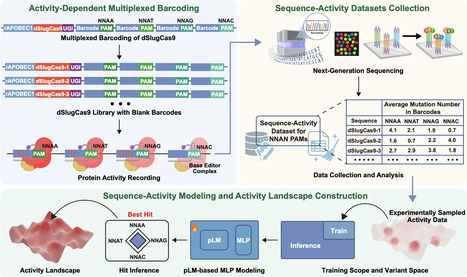
Protospacer adjacent motif (PAM) requirements constrain the targeting scope of CRISPR-Cas9 systems and limit genome editing applications that require precise nuclease positioning. Although broad-PAM and near-PAMless Cas9 variants have expanded the editable genome, robust targeting across certain PAM families remains difficult, particularly at NNAN PAMs. Here, we apply Sequence Display to generate multiplexed, large-scale sequence–activity datasets for Staphylococcus lugdunensis Cas9 (SlugCas9) across the NNAN PAM family, including NNAA, NNAT, NNAC and NNAG. These datasets quantitatively resolve how individual and combinatorial mutations reshape nuclease activity across distinct PAM contexts. By integrating Sequence Display-derived datasets with protein language models, we construct fine-grained activity landscapes and identify SlugCas9 variants with enhanced and broadened activity across NNAN PAMs. The resulting variants reprogram PAM recognition beyond the native G-compatible landscape of SlugCas9 and enable improved base editing at selected endogenous NNAN-constrained sites in cultured mammalian cells, including disease-relevant sites in APOC3 and PCSK9. Together, our results establish a strategy for reprogramming PAM preference in compact Cas9 nucleases and highlight Sequence Display as a general platform for evolving genome editors toward specific and difficult-to-access PAM spaces. Compact CRISPR-Cas9 enzymes are easier to deliver but recognize few targets. Here, authors use Sequence Display to generate large-scale SlugCas9 sequence–activity datasets and apply protein language models to engineer variants that recognize difficult NNAN PAMs and edit selected human genomic sites.
|
|
Scooped by
mhryu@live.com
October 30, 4:25 PM
|
Metal ion recognition in proteins emerges from coordinated effects of sequence patterning, hierarchical structure, and dynamic plasticity that promote high-affinity, ion-selective binding. Synthetic polymers, by contrast, offer broad chemical tunability but lack unified frameworks linking copolymer sequence and organization to function. Here, we position lanthanide-binding polymers as a tractable, technologically relevant model for importing protein-inspired design principles into synthetic macromolecules. We summarize approaches to quantify monomer patterning beyond coarse architectural classifications, enabling direct connections between polymer sequence and function. Using metalloproteins as conceptual inspiration, we examine coordination-dependent hierarchical structures in synthetic polymers, where noncovalent interactions drive reorganization across local and global length scales. We then highlight chain dynamics as an underexplored dimension of macromolecular design, where ion-dependent changes in mobility may couple to affinity and selectivity. Together, these sequence–structure–dynamics relationships provide a framework for developing polymeric chelators with protein-like metal recognition for applications in sensing, separations, and catalysis.
|
|
|
Scooped by
mhryu@live.com
Today, 11:00 AM
|
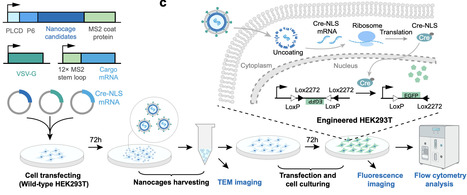
Safe and effective gene delivery remains a central challenge for therapeutic applications. While non-viral and viral vectors have enabled substantial progress, their reliance on non-human components often triggers immune responses, limiting their use in chronic treatments. Here, we develop DeepDelivery, an artificial intelligence-driven platform to identify human proteins with scaffold potential for mRNA delivery. Proteome-scale screening nominated 512 candidates, and experimental validation show that 12 of 15 selected human proteins functioned as scaffold components that facilitated particle formation and mRNA delivery within a modular engineering framework. Notably, several tripartite motif (TRIM) family proteins, typically linked to antiviral responses, exhibit strong assembly and delivery activity. Model interpretability and perturbation analyses identify TRIM domain features that influenced prediction scores and guide TRIM25-specific domain engineering to improve delivery. Together, these results establish a framework for mining the human proteome for scaffold components of programmable mRNA delivery systems and for further exploring the design space of human-derived delivery architectures. Protein-based carriers could provide biocompatible options for mRNA delivery. Here, authors develop an AI-guided platform to identify and engineer human-derived protein scaffolds that assemble into particles and support mRNA delivery in cultured cells.
|
|
Scooped by
mhryu@live.com
Today, 10:33 AM
|
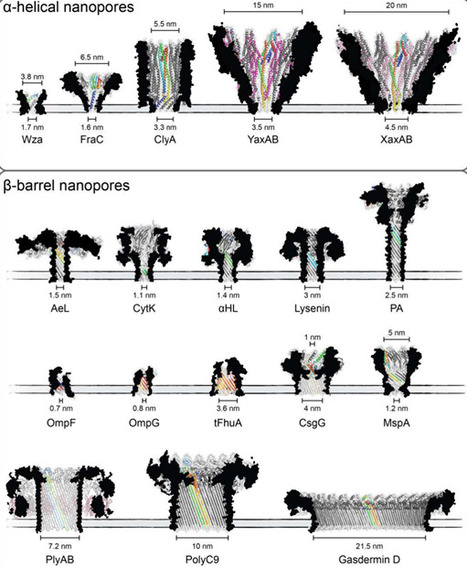
Protein-based biological nanopores have emerged as versatile tools for sequencing biopolymers, identifying molecules, and probing reactions at the single-molecule level. Many biological nanopores have been characterized, revealing the significance of nanopore size, shape, and chemical composition in molecular detection and discrimination. Advancements in understanding the nanofluidic properties of nanopores have complemented engineering approaches expanding the possible applications of nanopore technology. Through a combination of structural insights, rational design, systematic screening, and molecular dynamics simulations, researchers have developed nanopores capable of distinguishing between ions, nucleic acids, peptides, and folded proteins with remarkable specificity and sensitivity. Building upon three decades of progress, this Review highlights recent engineering innovations, discusses ongoing challenges, and explores the prospects in the field.
|
|
Scooped by
mhryu@live.com
Today, 10:13 AM
|
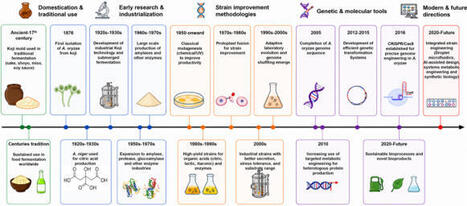
Filamentous fungi of the genus Aspergillus, because of their exceptional secretory capacity and metabolic versatility have been extensively applied in traditional food fermentation and industrial biotechnology for production of diverse bioproducts. Their history of domestication and industrial application has enabled major progress in enzyme production; however, challenges associated with the filamentous growth and strain engineering for future biomanufacturing development still remain. This review summarizes the advances across the spectrum of strain-improvement methodologies, from classical mutagenesis, protoplast fusion, genome shuffling, and adaptive laboratory evolution to the modern era of CRISPR enabled genome editing, synthetic biology, and systems-level metabolic engineering. Previous reviews have primarily focused on individual Aspergillus species, specific industrial products or particular strain improvement approaches. In this review, we provide a comprehensive overview of classical and modern strain engineering technologies and industrial scale up across a wide range of Aspergillus species for industrial enzyme production. In particular, emerging non-GMO evolution tools such as atmospheric and room temperature plasma (ARTP) mutagenesis, and modern molecular biotechnology coupled with microdroplet-based ultrahigh-throughput screening, now allow the researchers to generate and screen a large number of Aspergillus species mutants with single-cell precision. The discovery of high-performance strains with enhanced secretion, stress tolerance, substrate utilization, and favorable enzymatic profiles for food and bioprocessing applications has been accelerated by the strain innovations. Collectively, these advances establish A. oryzae and the related species as increasingly reliable, scalable, and programmable hosts that can meet the biomanufacturing requirements of future circular and sustainable bioeconomies.
|
|
Scooped by
mhryu@live.com
October 31, 5:42 PM
|
Long non-coding RNAs (lncRNAs) have diverse biological functions, but experimentally validated evidence remains scattered across the literature and is often context dependent. EVLncRNAs 4.0 (https://www.sdklab-biophysics-dzu.net/EVLncRNAs4/) updates our manually curated database of functional lncRNAs supported by low-throughput experiments. For this release, 16 581 publications indexed between 15 May 2023 and 15 May 2026 were retrieved and manually screened. Compared with EVLncRNAs 3.0, EVLncRNAs 4.0 contains 7808 functional lncRNAs (+26%) from 199 species (+23%), 2313 diseases (+34%), 28 757 curated functional records (+21%), and 18 380 molecular interactions (+25%). EVLncRNAs 4.0 also introduces two AI-assisted functions built on the curated evidence base. AI Search uses an enhanced retrieval-augmented generation framework with adaptive selection across Quick, Expanded, and Exhaustive retrieval modes and generates answers from retrieved EVLncRNAs records with PMID-linked citations. Benchmark evaluation showed complete request execution, high retrieval coverage and full citation validity within the supplied evidence context. Functional Overview retrieves and aggregates lncRNA- and species-specific curated records before generating concise evidence-based summaries. In both functions, language models synthesize retrieved evidence rather than serve as independent sources of biological knowledge. EVLncRNAs 4.0 therefore provides an expanded, experimentally grounded resource for accessing and interpreting functional lncRNA evidence across species and biological contexts.
|
|
Scooped by
mhryu@live.com
October 31, 5:11 PM
|
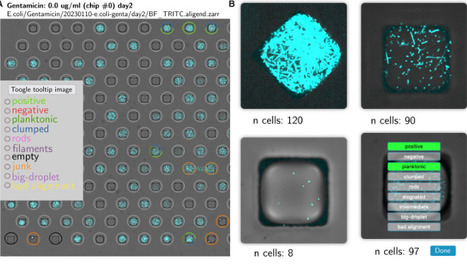
Bacterial morphology is modified by antibiotic stress depending on the antibiotic mechanism of action, while changes in morphology can contribute to cell survival. Here we present a workflow that generates morphological signatures for the progeny of individual bacterial cells across 168 antibiotic conditions. The workflow uses stationary microfluidic droplets to encapsulate and grow bacteria and confocal microscopy to image the droplet content. A custom image analysis pipeline labels morphologies in a subset of images to train a neural network. The network yields multidimensional morphological signatures from 82,000 droplets, showing the co-existence of different morphologies even for the progeny of individual cells. The signatures differ with antibiotic type and concentration, providing a way to distinguish antibiotics by their mode of action. Combined with digital detection of bacterial survival within droplets, this workflow provides a quantitative platform to investigate antibiotic resistance and identify the antimicrobial activity of unknown compounds.
|
|
Scooped by
mhryu@live.com
October 31, 5:02 PM
|
Biomolecular condensates have so far been studied in terms of their structural, compositional, and functional properties. However, condensate enzymatic activity - a key aspect of cellular metabolism - remains unexplored due to the complexity of the system. In this study, using a combination of experimental, computational and theoretical techniques, we have discovered that the non-equilibrium activity which originates from catalytic reactions couples with the environment through various feedback mechanisms across five orders of magnitude of length scales. We observe that condensed enzymes catalyze more rapidly in the presence of crowding proteins and show that the increased enzymatic activity within these droplets stems from the emergence of lower-energy protein conformations induced by the highly crowded environment. Despite the crowding in the environment of the droplet, which might suggest an effective increase in its overall viscosity, we find that it becomes more agile, as evidenced by the observation of enhanced diffusion and macroscopic flow, due to the enzymatic activity. These findings shed light on the dynamic interplay between enzymatic activity, composition and crowding in condensates, and their roles on the mobility and accessibility of various functional units in these environments, expanding our understanding of liquid-liquid phase separation in metabolically active conditions. Enzymes operate in highly crowded cellular environments, yet the impact of crowding on their function remains poorly understood. Here, the authors demonstrate that enzyme activity increases molecular mobility in crowded protein droplets, suggesting a feedback mechanism between catalysis and the physical properties of the surrounding environment.
|
|
Scooped by
mhryu@live.com
October 31, 4:25 PM
|
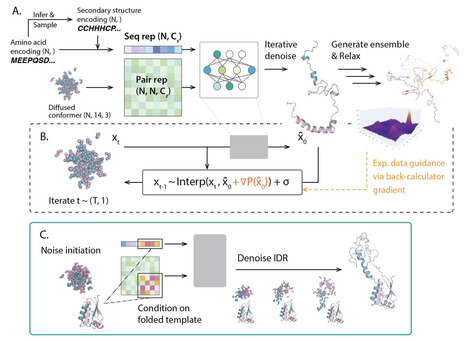
Although machine learning has transformed protein structure prediction of folded protein ground states with remarkable accuracy, intrinsically disordered proteins and regions (IDPs/IDRs) are defined by diverse and dynamical structural ensembles that are predicted with low confidence by algorithms such as AlphaFold and RoseTTAFold. We present a machine learning method, IDPForge (Intrinsically Disordered Protein, FOlded and disordered Region GEnerator), that exploits a transformer protein language diffusion model to create all-atom IDP ensembles and IDR ensembles that maintains the folded domains. IDPForge does not require sequence-specific training, back transformations from coarse-grained representations, nor ensemble reweighting. The created IDP/IDR conformational ensembles show good agreement with both NMR and SAXS solution experimental data, and options for biasing with experimental restraints are available if desired. IDPForge with these diverse capabilities facilitates integrative and structural studies for proteins that contain intrinsic disorder, and is available as an open source resource for general use. Intrinsically disordered proteins and regions (IDPs/IDRs) are defined by diverse structural ensembles. We present IDPForge that exploits a transformer protein language diffusion model to create all-atom IDP and IDR ensembles that maintain folded domains with options to conform to experimental data.
|
|
Scooped by
mhryu@live.com
October 31, 10:28 AM
|
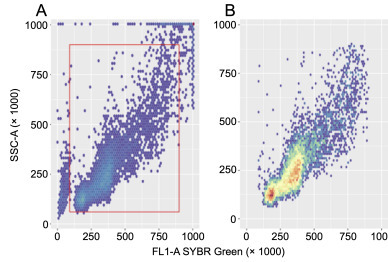
Karyotypic variation in fungal populations from ecological, clinical, and industrial environments and is also a hallmark of many cancers. The evolutionary dynamics of karyotypic vriants (i.e., changes in the number of chromosomes, either as complete sets or single chromosomes) are the same as any de novo mutation. To quantify karyotypic subpopulations within evolving populations, an unbiased computational method is required to identify subpopulations and quantify their abundance. Flow cytometry is the standard method to measure the genome size from large populations of individual cells. Cell populations typically include cells in all stages of the cell cycle (G0/G1 before DNA replication, S phase during replication, and G2/M after DNA replication but before cell division). Existing mathematical models can be fit to genome-size distributions to determine the base ploidy of a population, but existing algorithms assume a single base ploidy. Mixed-karyotype populations therefore require manual gating to subdivide the flow cytometry data before analysis, which introduces bias, as it is not always clear where or when gates should be drawn. To overcome this, we developed a new method that identifies and quantifies karyotypic subpopulations from flow cytometry data. The open-source R package ploidyPeaks builds on existing Bioconductor tools to import and manipulate standard .fcs flow cytometry files. Using reference populations of known ploidy, we established thresholds to distinguish single-genome size populations and identify candidate mixed-karyotype samples. We then developed a peak-detection algorithm to identify G0/G1 and G2/M peaks, resolve karyotypic subpopulations within mixed populations, and apply nonlinear least-squares fitting of the Dean-Jett-Fox cell-cycle model to each subpopulation, providing a confidence measure for model fit. Compared with existing methods, our approach quantifies genome size in mixed-karyotype populations without manual intervention while providing an objective measure of model fit. We demonstrate the utility of this method on 240 replicate populations initiated from 20 Candida albicans genetic backgrounds evolving for 100 generations to the antifungal drug fluconazole.
|
|
Scooped by
mhryu@live.com
October 30, 4:48 PM
|
Although the term pangenome originated in the study of microbial species, recent advances in eukaryotic pangenomics have been driven largely by the need to manage the substantial computational challenges posed by population-scale eukaryotic datasets. This review evaluates the extent to which existing eukaryotic pangenome tools and methods can be extended to microbial species. We first survey current eukaryotic and microbial pangenomic approaches and then examine opportunities and challenges in adapting eukaryotic methods to microbial genomes, with particular emphasis on scalability, data quality, evolutionary complexity, and benchmarking. Finally, we highlight areas where existing approaches generalize well and where substantive redesign and redevelopment are needed.
|
|
Scooped by
mhryu@live.com
October 30, 4:43 PM
|
Codon optimization (CO) is a key design variable in bio-therapeutics that is used to enhance expression of recombinant proteins, gene therapies, and vaccines. Although synonymous codon substitutions were historically considered neutral, codon choice can influence messenger RNA (mRNA) stability, translation kinetics, cotranslational folding, and immunogenicity. Current optimization strategies integrate computational parameters including codon adaptation indices, tRNA availability, mRNA structure, cytosine–phosphate–guanine dinucleotide content, codon pair bias, and machine learning approaches to balance expression and product quality. Additionally, dynamic tRNA modifications within the epitranscriptome modulate codon-biased translation in a context-dependent manner. While CO has not been implicated in adverse clinical outcomes, its context-dependent effects on protein conformation, post-translational modifications, and immune responses necessitate rigorous characterization. This opinion article presents our viewpoint on mechanisms, applications, and regulatory considerations for CO in biologics.
|
|
Scooped by
mhryu@live.com
October 30, 4:35 PM
|
Iron is indispensable for most organisms, but it is often not easily available in the natural environments. This constraint has considerable impact on cyanobacteria, which require large amounts of iron to support several physiological processes, prominent among them being photosynthesis and, in some species, nitrogen fixation. To overcome iron limitation, many cyanobacteria produce low-molecular-weight, strong iron-sequestering molecules called siderophores, and employ specialized transport systems for environmental iron acquisition. Although these systems share similarities with those of well-characterized heterotrophic bacteria, our understanding of siderophore-mediated iron uptake in cyanobacteria remains limited. To date, only a handful of cyanobacterial siderophores have been structurally identified, and few genes involved in their biosynthesis, transport, and regulation have been reported, but a complete understanding of these processes remains lacking. This review first briefly discusses the well-established siderophore biosynthesis, transport, and regulatory systems of the model heterotrophic bacteria E. coli and Pseudomonas aeruginosa, as a comparative framework. It further discusses the current understanding of siderophore systems in cyanobacteria, highlighting similarities and differences with heterotrophic bacteria, species-specific variations among cyanobacteria, and major knowledge gaps. The review also discusses the ecological significance of cyanobacterial siderophores and their emerging applications in heavy metal bioremediation. Overall, this review identifies important directions for future research, including expanded structural characterization of cyanobacterial siderophores, deeper investigation of their biosynthesis, transport, and regulatory pathways, and improved understanding of their ecological functions and environmental applications. Addressing these gaps will strengthen our mechanistic understanding of siderophore-mediated iron uptake in cyanobacteria and its environmental relevance.
|
|
Scooped by
mhryu@live.com
October 30, 4:27 PM
|
Per- and polyfluoroalkyl substances (PFAS) are persistent fluorinated contaminants of growing environmental concern, yet rapid methods for assessing their biological effects remain limited. This study evaluated lux-marked Pseudomonas putida F1 Tn5 luxCDABE and P. putida 12708 Tn5 luxCDABE as whole-cell biosensors for detecting sublethal PFAS toxicity. Fluoride bioassays confirmed both strains tolerated up to 1,000 mg L−1 fluoride without measurable bioluminescence inhibition, supporting their suitability for PFAS exposure studies. Growth and bioluminescence responses were then assessed in M9 minimal medium following exposure to PFOA, PFNA, and PFHxS. Conventional growth measurements showed limited effects across tested concentrations, with strain-specific reductions observed mainly in P. putida F1 Tn5 luxCDABE. Bioluminescence revealed clearer compound- and concentration-dependent responses. PFOA and PFNA caused significant inhibition of peak bioluminescence in P. putida F1 Tn5 luxCDABE, while P. putida 12708 Tn5 luxCDABE showed a variable response, including increased luminescence following PFOA exposure and inhibition at higher concentrations of selected PFAS. These findings demonstrate that lux-marked P. putida biosensors are able to detect PFAS-induced metabolic stress with greater sensitivity than conventional growth assays and highlights their potential as rapid tools for ecotoxicological screening of fluorinated contaminants.
|


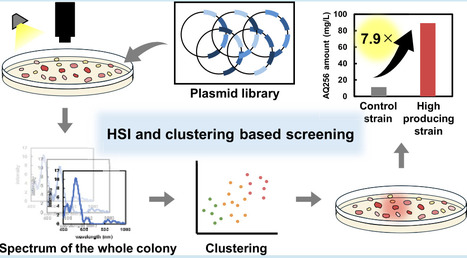









1str, tool, reporter, Fluorescence spectral data of entire colonies on library plates were acquired using a hyperspectral (HS) camera. (A) Experimental flow of clustering model-based screening. Raw fluorescence spectra of whole colonies were acquired using HSI. Clustering analysis was then performed based on spectral similarity to group colonies into distinct clusters